Pixel

Pixel Updates & Events

Server Updates & Events

Announcements

DEV Community

Why is my AWS bill so high when traffic is flat?

An AWS bill that climbs while traffic stays flat usually has one of three causes: data nobody deletes keeps piling up, a discount has ended, or a new charge started on a set date. To see why your AWS bill is so high, compare the month before the climb with the latest one in Cost Explorer. Compare two months in Cost Explorer Open the free Compare view under Report parameters, pick two of the last 13 months and group by service. According to the cost comparison documentation, Compare shows the three biggest changes and names the reason for each: usage, discounts, or other charges and credits. Usage rising by a similar amount every month points to data that only grows. If traffic is flat and AWS puts a jump down to discounts or credits, a Savings Plan or reservation has usually expired, or your credits have run out. Then filter to the growing service in the normal Cost Explorer view and group it by Usage type. The chart for this part is in the original post. A slow climb usually triggers no alert. According to the Cost Anomaly Detection FAQ, the default setup alerts only when an anomaly exceeds both 40% of expected spend and $100. A budget with a lower threshold warns sooner; see the post on AWS budget alerts. S3 versions, ECR images and RDS storage With versioning on, S3 keeps every version of a file as a separate, full object at the normal rate. Deleting a file frees nothing, because S3 only adds a delete marker. Incomplete multipart uploads grow the same way and are billed until someone completes or aborts them. S3 Storage Lens shows both in two free metrics, Noncurrent version bytes and Incomplete multipart upload bytes. ECR, the container image registry, also fills up when every deploy pushes a new image. A lifecycle policy removes old images by count or age. Check it in the lifecycle policy preview first, as AWS advises, and keep enough recent images to roll back. On RDS the disk grows. With storage autoscaling on, AWS enlarges it by itself when space runs low but never shrinks it, so you keep paying for the added gigabytes after the data is deleted. Manual RDS snapshots ignore the retention period and stay until you delete them. CloudWatch logs never expire by default. I cover them, and EBS snapshots left behind by old scripts, in what I check in an AWS cost audit. A lifecycle rule for S3 The rule below covers the whole bucket: it deletes versions that have been noncurrent for 30 days and aborts uploads older than 7 days. The put command replaces every existing rule on the bucket, so read the current rules first and copy any you want to keep into the file. If one of them keeps old versions longer than 30 days, leave this rule out: where rules overlap, S3 honours the shorter expiration. The commands are for AWS CLI v2. aws s3api \
get-bucket-lifecycle-configuration \
- -bucket my-bucket
Save the rule as lifecycle.json: {
"Rules": [
{
"ID": "cleanup",
"Status": "Enabled",
"Filter": { "Prefix": "" },
"NoncurrentVersionExpiration": {
"NoncurrentDays": 30
},
"AbortIncompleteMultipartUpload": {
"DaysAfterInitiation": 7
}
}
]
}
aws s3api \
put-bucket-lifecycle-configuration \
- -bucket my-bucket \
- -lifecycle-configuration \
file://lifecycle.json
Deleted versions cannot be recovered, so if you reach for old files months later, raise NoncurrentDays. When a Savings Plan or reservation ends Neither a Savings Plan nor a reservation renews itself. Once an RDS reservation ends, the database is billed at the on-demand rate. Before a Savings Plan ends, you can queue a new plan or click Renew Savings Plan. Turn on the expiry email under Manage alert subscriptions on the Savings Plans page. Year three of RDS Extended Support RDS adds an Extended Support charge for MySQL and PostgreSQL versions whose standard support has ended, and doubles it in year three. According to RDS pricing on 11 November 2026, a 2-vCPU database on MySQL 5.7 in Frankfurt (eu-centr...

Powered by Readybot.io

**DEV Community** ## Why is my AWS bill so high …

DEV Community

How to Catch Missing .env Variables and .env.example Drift Before Production Deploy

Originally published at umutgungorr.com. How to stop silent .env vs .env.example configuration drift and undocumented os.getenv calls in CI before a missing environment variable breaks production. Why code that passes locally crashes on deploy Adding a new key to your local .env file while building a feature takes seconds. Forgetting to mirror that key in .env.example and your deployment environment usually stays invisible until production traffic hits that branch and fails with a KeyError or empty string. Missing keys are only half the problem: stale variables accumulate in templates over time, new teammates cannot tell which keys are actually required, and local onboarding slows down. Step 1: Enforce the .env ↔ .env.example contract in CI Treating configuration drift as a build failure rather than a passive warning is the cleanest fix. The zero-dependency envdoctor-cli package compares .env against .env.example and exits non-zero whenever keys drift. pip install envdoctor-cli

.env ile .env.example arasındaki eksik veya fazla anahtarları kontrol et

envdoctor check --strict

Eksik anahtarları gerçek değerleri sızdırmadan maskeli yer tutucuyla ekle

envdoctor sync
Step 2: Surface undocumented env vars in source code with AST Comparing two env files is not enough on its own: a developer may add os.getenv("NEW_WEBHOOK_SECRET") in Python code without documenting it in either .env or .env.example. Regex greps misfire on comments and string literals, whereas Python AST analysis extracts actual environment lookups directly from the syntax tree. # Kaynak kodda os.getenv / os.environ çağrılarını tara ve CI için JSON üret
envdoctor audit --format json
Step 3: Add a 5-line gate to GitHub Actions Running both template validation and AST auditing on every pull request catches undocumented environment keys before the branch is merged. The check validates key names only and never transmits secret values. name: Env Contract Check
on: [pull_request]
jobs:
envdoctor:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: actions/setup-python@v5
with:
python-version: '3.12'
- run: pip install envdoctor-cli && envdoctor check --strict && envdoctor audit
References EnvDoctor project page and architecture notes PyPI: envdoctor-cli package GitHub: umutgungorr/envdoctor Designing CLI Tools That Earn Trust

Powered by Readybot.io

**DEV Community** ## How to Catch Missing .env Variables and …

** Latest from PC Gamer **

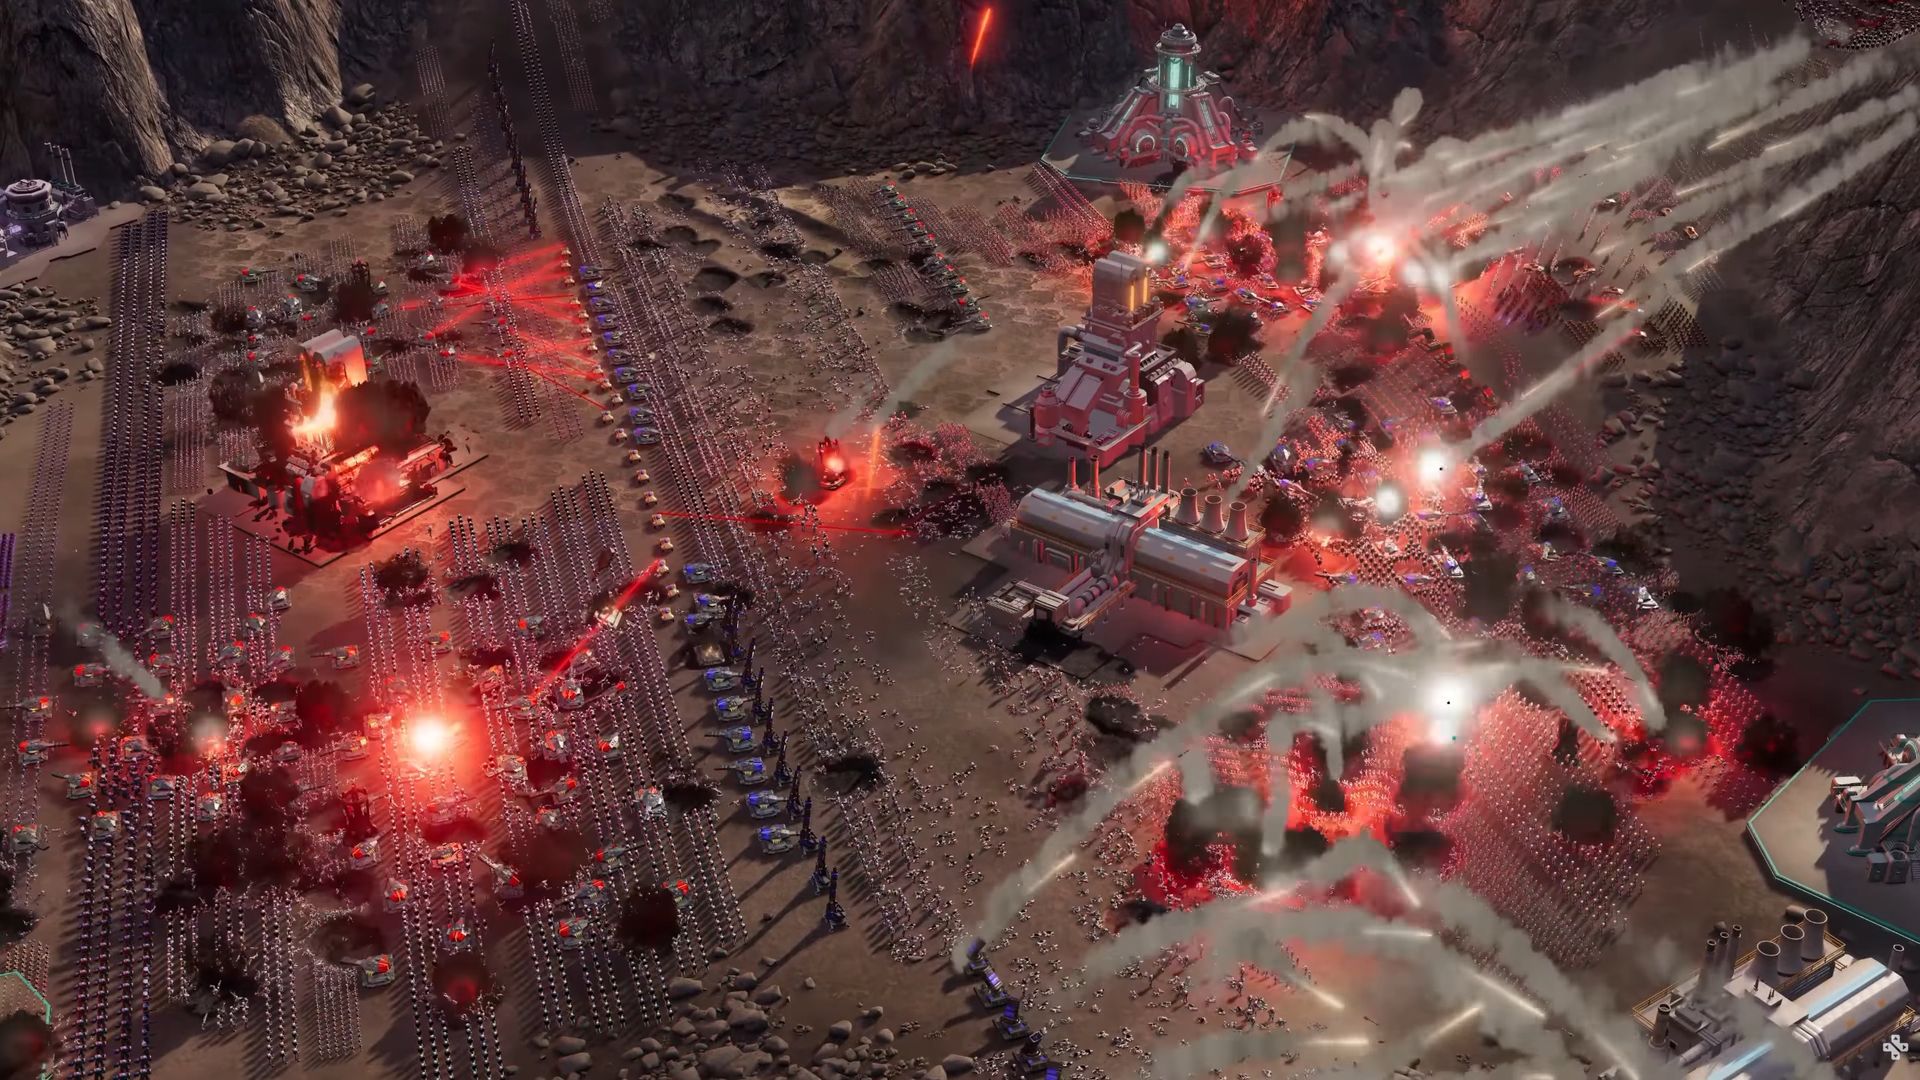
This RTS inspired by Star Wars: Empire at War promises colossal space encounters and planetary battles with 'hundreds of thousands of units'

Horu is expected to launch at the end of next year.

Powered by Readybot.io

** Latest from PC Gamer ** ## This RTS inspired …

IGN India Pc

Fortnite - Official Treasure Hunters Week 3 Gameplay Trailer

Check out the Fortnite Treasure Hunters Week 3 gameplay trailer as the duo you didn't know you needed, Hatsune Miku and Kasane Teto, land on the Island! See the two iconic virtual singers in action in Fortnite Treasure Hunters, available now.

Powered by Readybot.io

**IGN India Pc** ## Fortnite - Official Treasure Hunters Week …

DEV Community

Thread Milling vs Tapping vs Rolling: What Actually Changes in the Quote

Six M3 taps in one afternoon. That's what started this. A batch of 17-4 PH stainless parts, M3 × 0.5, 8 mm deep, blind. The operator was running them on a VMC with a tapping cycle, and by the third hour he'd broken six taps and had two stuck in the holes — which meant two scrapped parts, because a broken tap in 17-4 is not coming out. Nothing was wrong with the taps. The problem was the method. There are four ways to put a thread in a part, and they are not interchangeable. Each one changes the quote, the risk, and sometimes the design. Tapping A cutting tap removes material. It's fast, the tooling is cheap, and on aluminum and mild steel it's the default answer. Where it goes wrong: chip evacuation. In a blind hole, chips have nowhere to go except back up the flutes, and the deeper you go the worse it gets. Form-factor taps (spiral flute, spiral point) help, but below about M4 the tool cross-section is so small that a chip jam equals a snapped tap. In 17-4 PH, work-hardening makes it worse. The material gets harder where the tap rubs, so a slightly dull tap doesn't cut — it burnishes, then breaks. Form tapping (thread forming) No chips at all. The tool cold-forms the material instead of cutting it. The resulting thread has continuous grain flow and is measurably stronger in fatigue than a cut thread. Two catches. First, the tap hole is different — form tapping needs a larger pilot hole than cutting (roughly the pitch diameter minus half the pitch, but check the tap maker's chart). Second, it takes more torque, which means more spindle power and a rigid setup. On thin-walled parts it can distort the wall. Works well in aluminum, brass, and low-carbon steel. Poor in cast iron and anything brittle. Thread milling A single-point or multi-flute thread mill follows a helical path. The tool is small relative to the hole, so there is no chip packing problem, and if the tool breaks it breaks into small pieces that flush out instead of wedging in the hole. This is the answer for hard materials, large threads, and any hole where a broken tap would scrap the part. It also lets you cut a thread with an interrupted profile, or reach a thread right up to a shoulder where a tap couldn't. The cost: cycle time. A single-point thread mill on an M3 hole takes maybe 10–20 seconds; a tap takes two. And the machine needs helical interpolation, which every modern VMC has but older ones may not. Where thread milling wins economically: M16 and up, where the tap is expensive and the torque is high. At M20 in steel, a thread mill often costs less per part than the tap does per hole, because the mill lasts hundreds of holes and the tap doesn't. Thread rolling (external) Cold-forming an external thread between two or three dies. This is a different animal — it produces the strongest thread available, with uninterrupted grain flow and a compressive residual stress at the root. For studs, shafts, and anything fatigue-critical, it's the right process. But it needs a dedicated machine or a rolling attachment, and it only does external threads. Job shops usually send this out. What it does to the quote Rough hierarchy for a small thread in a small hole: Tapping, aluminum, through hole: cheapest, no discussion needed. Form tapping, aluminum: same order of magnitude, better thread. Tapping, stainless or hardened: risky. Price it with a breakage allowance, or don't price it at all. Thread milling, any material: 2–5× the cycle time of tapping, near-zero scrap risk. Thread rolling: a separate operation, quoted separately. The trap is quoting tapping on a material where breakage is likely. If the shop doesn't add a risk allowance, they either eat the scrap or the part arrives late. Both are worse than a slightly higher price. What to put on the drawing Thread callout alone isn't enough. Specify: Class: 6H for internal, 6g for external (or 2B/2A in inch). Depth: thread depth and drill depth separately. A blind hole needs the drill to go deeper than the thread, an...

Powered by Readybot.io

**DEV Community** ## Thread Milling vs Tapping vs Rolling: What …

DEV Community

llama.cpp Just Hit 1.0, and Local AI Finally Has a Promise to Stand On

Have you ever built something on top of a tool that changed underneath you? You write code against a library, everything works, and then one update quietly moves a function or renames a setting. Nothing explodes. Your code just stops compiling on a Monday morning, and you spend the day figuring out what moved. If you run AI models on your own computer, you have probably lived this. On November 13, the project at the bottom of that whole stack finally made a promise that it will stop happening without warning. llama.cpp, the open-source engine that runs large language models on ordinary hardware, released version 1.0.0. The engine you already use, even if you never installed it First, a quick explainer, because llama.cpp is one of those things that is everywhere and invisible at the same time. It is not a chatbot and not a model. It is the engine: a small, fast program written in C and C++ that loads a model file and runs it on your laptop, your desktop, or a server. You have probably used it without knowing. Tools like Ollama and LM Studio, the friendly apps people use to chat with models on their own machines, build on llama.cpp underneath. When you run a model locally instead of sending your prompts to someone else's cloud, there is a good chance llama.cpp is doing the actual work. The project has been around for about three and a half years, and for all that time it versioned itself with plain build numbers: b1234, b12359, and so on. Each release was just the next number in line. There was no way to look at a version number and know whether upgrading would break your code. Photo by Kevin Ache on Unsplash What 1.0 actually promises Version 1.0 changes that, and the change is a promise, not a feature. From now on, llama.cpp and its underlying tensor library, ggml, follow semantic versioning. The rule is simple: a breaking change to the public C API only ever arrives with a major version bump. A new feature or new model support gets a minor bump. A bug fix gets a patch bump. Think of it like a building finally getting its foundation inspected and certified. The house does not look any different from the street. But now there is a document saying which walls are load-bearing, and nobody is allowed to move one without telling you first. That is what 1.0 is: a signed contract between the maintainers and every developer building on top of them. And the timing makes sense. The announcement says many downstream applications already depend on the project, and it now supports more than 150 model architecture variants. When that many apps stand on your work, a stable public API stops being a nice idea and becomes the job. The cleanup that came with it A 1.0 release is also a good moment to throw things out, and this one did: the deprecated public API is gone, including 35 deprecated functions. There are smaller improvements too, like FP8 key-value caches that use less memory and security hardening for llama-server. But none of that is the headline. The headline is the version number itself. The honest fine print Here is the part worth reading twice. A stable version number does not mean nothing will ever break. The promise covers the public C API, the headers in the include directory. It does not cover every command-line flag or every model file forever. And 1.0 itself is a breaking change if your code still calls one of those 35 removed functions: it will fail at compile time, which is exactly the kind of break the new rules are designed to announce in advance next time. That is the deal, and it is a fair one. You get a clear signal about what changed and how much it matters. In return, the maintainers get to keep moving fast without quietly pulling the floor out from under you. So if you build anything that runs models locally, or you are thinking about it, this quiet release matters more than most loud ones. The engine underneath local AI just grew up a little. It put its promise in writing. What would you build if you could tru...

Powered by Readybot.io

**DEV Community** ## llama.cpp Just Hit 1.0, and Local AI …

DEV Community

How Many Shops Should You Quote? The Math Behind 2 vs 5

The question comes up in almost every sourcing thread: how many shops should I quote before I pick one? Most answers are folklore — "always three," "at least five," "get seven and average them." None of those survive contact with what actually happens when you send an RFQ. Here's what the numbers look like. The first quote is an anchor, not information Whatever the first shop comes back with becomes your reference point. If it's $18 and the market is $12, every subsequent quote looks cheap by comparison and you'll accept $14 thinking you did well. This is a real effect and it's well documented in procurement. The practical countermeasure is to send all RFQs on the same day, and not to open any response until you've collected all of them. Sounds bureaucratic; it changes outcomes. The spread between shops is mostly not about price When three shops quote $12, $14, and $31 for the same drawing, the $31 is rarely "expensive." Usually one of four things happened: They read the drawing differently. One shop assumed ±0.05 on the bore, another read it as ±0.005 because the note was ambiguous. They included something the others didn't. Material cert, FAI report, surface treatment, packing. They don't want the job. A shop with full 5-axis capacity quoting a 50-piece turning job is signaling. They made an error. Setup time estimated wrong, material price stale. Only one of those four is a price difference. The other three are information problems, and more quotes won't fix them — a better RFQ will. A 3× spread is a red flag on your RFQ, not on the market. Diminishing returns kick in around four The useful information from quotes is the distribution. With two quotes you have a range but no idea where the median sits. With three you can see if one is an outlier. With four you can usually tell whether the low one is credible or just optimistic. By the fifth quote, you're mostly learning the same thing again. The fifth and sixth responses move your expected value by a few percent while costing you another week of clarification emails. Four is the point where the marginal quote stops changing the decision. The real cost is clarification, not the quotes themselves Every shop asks some version of the same five questions: What material, and is the cert required? What quantity, and is that one lot or scheduled releases? Which dimensions are critical? What surface finish / treatment? Which Incoterm, and which port? If you answer those five in the RFQ package, response time drops from a week to two days and the quotes become comparable. If you don't, you'll spend that week answering the same email four times, and the quotes you get back won't be for the same scope. So the cheapest thing you can do is write the RFQ properly, not send it to more people. What a complete RFQ package contains For a machined part, this is the baseline: Item Why it matters 2D drawing with GD&T The 3D model doesn't carry tolerance intent STEP file Geometry, for CAM and stock calculation Material + condition 6061-T6 ≠ 6061-T651 for stress and price Quantity + lot structure 100 in one lot ≠ 4 × 25 Critical dimensions marked Saves the shop guessing which features to control Surface treatment spec Anodize type/color/thickness, or "none" Inspection requirement FAI, sampling, CMM report, or none Incoterm + destination EXW Shenzhen vs DDP Chicago is a 30% swing Target date Design freeze vs production launch changes urgency Nine lines. Fills one email. Turns four incomparable quotes into four comparable ones. When to quote more than four Three legitimate cases: Non-standard material. If you need Inconel 718 or a specific PEEK grade, most shops don't stock it, and their quotes include different lead times from different distributors. Four quotes on the material alone may not be enough. A process you can't evaluate. Thread rolling, EDM, vacuum brazing, passivation — if you don't know what the process should cost, more data points help you build a range. A first order with a new s...

Powered by Readybot.io

**DEV Community** ## How Many Shops Should You Quote? The …

DEV Community

GitHub Actions step output empty: the missing or misspelled step id

A GitHub Actions step output empty in a later step is a reference problem rather than an expression problem. The expression is valid, so nothing is rejected and nothing turns red; a property that is not there evaluates to an empty string, and every step downstream behaves as though the value was never set. Two conditions get a step into the context: it declared an id, and it has already run. Everything else reads back as an empty string. What this error means The workflow is valid, the run is green, and something downstream ran with a blank where a version, a tag or a path should have been. A condition gated on the value never fires, or fires every time, depending on which way round the comparison was written. A command receives an empty argument and either fails with a message about the argument or succeeds against the wrong target, which is the expensive version. Dumping the whole context is the usual next move and it produces the same puzzle in a smaller form: an empty object rather than a listing. Nothing in the log says why, because from the parser point of view nothing went wrong: it was asked for a property, the property was not there, and it returned what the documentation says it returns. ```Actions log, quoted from actions/toolkit#338 (timestamps removed) [group]Run echo "$STEPS_CONTEXT" shell: /usr/bin/bash -e {0} env: STEPS_CONTEXT: {} [endgroup]

Common causes

The producing step has no id

The common one, and the one that makes a context dump come back as an empty object. A step that writes to the output file without declaring an id has done the work and thrown away the label, so nothing can name it.

The id or the output name does not match

A rename on one side, a hyphen against an underscore, or a difference in case. The lookup misses and returns an empty string, so the workflow keeps running with a blank. Nothing compares the two spellings for you, which is why this survives review more often than it should.

The reference runs before the step it names

The context only holds steps that "have already run", so an expression in an earlier step, or in a job-level key evaluated at planning time, reads nothing. In our experience this arrives when steps are reordered and a condition that used to sit at the bottom ends up above the step that feeds it.

The step is in another job

A second job has its own context and cannot reach the first one. The value has to be promoted to a job output and read through needs, and a job that is not named in needs cannot read it even then, because that context holds direct dependencies only.

How to fix it

Declare the id on the step that sets the output

  1. Add id: to the producing step and use the same value in every reference.
  2. Keep the output name identical to the key written into the output file, including case.
  3. Put the reference after the producing step in the same job.

Print the value before you branch on it

One echo step tells you whether the output exists, which no condition can. Leave it in while you are wiring up a new output and remove it once the workflow is stable, or keep it behind a debug input if the output feeds anything expensive.

.github/workflows/release.yml (illustrative) - run: echo "meta.tag is [${{ steps.meta.outputs.tag }}]" Promote it to a job output for anything cross-job Declare outputs on the producing job, build each entry from the steps context, and read it from a job that names the producer in needs. This is also the only way to get a value into a job-level key such as runs-on or a job condition, neither of which can see steps. The producer below emits one JSON array, which the next fix expands into a matrix..github/workflows/ci.yml (illustrative) jobs: plan: runs-on: ubuntu-latest outputs: shards: ${{ steps.calc.outputs.shards }} steps: - id: calc run: echo 'shards=["1","2","3","4"]' >> "$GITHUB_OUTPUT"

Cast it back when you need a type

Because the value is text by the time anything...

Powered by Readybot.io

**DEV Community** ## GitHub Actions step output empty: the missing …

DEV Community

Reading a CMM Report: What the Numbers Actually Tell You

A buyer forwarded me a twelve-page CMM report last month with one line: "So does this part pass or not?" He'd had the report for two weeks. He'd printed it. He just couldn't tell what the numbers meant. That's normal. A coordinate measuring machine report is a technical document written for the person who programmed the measurement, not for the person making the purchasing decision. Here's how to read one in about five minutes. Start at the header, not the data The first page will have a block of parameters. Four of them matter: Temperature. CMM measurements are valid at 20 °C. If the part was measured at 26 °C and the report doesn't mention compensation, every dimension on a 100 mm aluminum feature is off by roughly 14 µm — which is larger than a ±0.005 mm tolerance. Not every shop logs this. The ones who do are telling you something about their process. Probe and stylus. A 2 mm ruby ball cannot measure into a 1 mm hole. If the report shows a small-hole diameter measured with a stylus that physically couldn't fit, the number is extrapolated, not measured. Program version and date. The report should say when it was run and with what program. A report dated three weeks before the shipment is a report about a different part. Datum definition. Look at which datum is primary. If the drawing says datum A is the large face and the report uses datum A as the bore, none of the position tolerances mean what you think. Then find the tolerance column, not the actual column People read CMM reports by scanning the "Actual" column and comparing to the nominal. That's backwards. Read the tolerance column first. It tells you what the shop thought you asked for. Then read actual. Then read deviation. The deviation column — actual minus nominal — is where problems show up, because a part can be inside tolerance and still be drifting toward one edge in a way that predicts the next batch will fail. If you see a column of deviations all positive and near the limit, that's a process trending out, even though nothing is out of spec today. Understanding what the columns are A typical line looks like this: Feature 12 Ø8.000 ±0.010 Actual 8.004 Dev +0.004 Out 0.006 OK
Nominal and tolerance from the drawing. Actual is what the machine found. Dev is the signed difference. Out (or "Out of Tol") is how much room is left before the limit. Sometimes shown as a percentage. Status is the pass/fail. For position tolerance, the number after ⌀ is a diameter zone, and the actual is usually reported as a diametral deviation, not a radius. Confusing the two is a common misread — a 0.02 position result is a 0.01 radial offset. GD&T modifiers change the answer Three modifiers show up constantly and each one changes the arithmetic: Ⓜ (MMC — maximum material condition). On a position callout, MMC gives you a bonus tolerance. If a hole is at ⌀8.05 when MMC is ⌀8.00, you get 0.05 of extra position tolerance. A report showing a position result that looks over tolerance may be perfectly valid once the bonus is applied. Check whether the report applied it; many don't, and the shop has to explain it manually. Ⓛ (LMC). Same idea in the other direction, used for wall thickness and clearance. Ⓟ (projected tolerance zone). Common on threaded holes. The tolerance zone starts above the surface, not at it. If the report measures at the surface, the result is meaningless. If the report doesn't state which modifiers were applied, ask. It's a two-line email and it's the difference between a real rejection and a misunderstanding. What CMM can't tell you Worth knowing before you reject a part based on a report: Small deep holes. Below about ⌀2 mm with depth over 5× diameter, the stylus can't reach the bottom properly. Reports may show a value that's really a partial measurement. Soft materials. Probe force deforms aluminum and plastics slightly. The measured diameter may not be the free-state diameter. Surface finish. CMM gives you geometry, not Ra. A separate surface roug...

Powered by Readybot.io

**DEV Community** ## Reading a CMM Report: What the Numbers …

DEV Community

Task Queue Retry Called The Customer Twice And An Exists Check Will Not Stop It

By Rokas Remeika. Published 22 September 2026. An at-least-once task queue retrying a telephony placement can ring a person twice, even if you check whether a call record already exists. This happens because the platform's native webhooks can create the call record before your dial RPC returns, and because a queue's retry timeout often fires while the first attempt is still ringing. To fix it, you need two markers. First, a post-placement marker written only by your dial code to prove the call happened. Second, a pre-placement attempt marker that locks the number for a window sized to your ringing timeout plus the queue's acknowledgment budget. Symptoms An at-least-once task queue retries the outbound dial task, and the same person is called twice within a minute. The queue metrics show only one logical task being processed, but the carrier logs show two distinct INVITEs leaving your infrastructure. The guard clause most people reach for (checking if the call record already exists before dialing) either never fires, or it fires on the first attempt and blocks a call that was never actually placed. The trap worth stating plainly: "does a record for this call exist" feels like idempotency and is not, as soon as more than one component can create that record. What is actually happening Two separate problems stack together to defeat a basic existence check. First, the call record is rarely authored by a single writer. The platform's native room-started webhook is fast and can easily create the record before the dial RPC returns. Because webhooks and the dial process run concurrently, the record existing is not evidence that a dial happened. An existence check in this state is simply reading a marker somebody else wrote. Second, the dangerous window occurs exactly between the moment we start placing the call and the moment we record the successful placement. Outbound ringing takes tens of seconds. A task queue that retries based on an acknowledgment timeout or visibility budget will re-enter the dial pipeline exactly during this window. Because the first attempt has not returned yet, nothing has been written to confirm placement. By definition, the existence check allows the second attempt through, resulting in a duplicate call. How to confirm it Log every queue redelivery of a dial task as an explicit event. This makes retries visible as events rather than being inferred from duplicate INVITEs. Correlate the webhook arrival time with the dial RPC return time for a single session. Expect to see the platform's room-started webhook arriving and writing to your database before the dial RPC completes its execution, proving that record existence is untrustworthy as an idempotency key. Measure the time from the attempt marker being written to the placement marker being written, per call. Count attempts refused by the in-flight window separately from attempts refused as already placed. How it works To prevent double-dials under queue retries, I use two markers with entirely different jobs. Relying on document existence is fundamentally flawed when multiple writers are involved. You have to pick fields that only the dial path can write, and check those fields exclusively. First, a post-placement marker serves as the final proof that a dial actually happened. This is written only by the dial path, and only after the placement RPC returns successfully. You check this field to know if the side effect is complete, never the bare document existence. Second, a pre-placement attempt marker closes the in-flight window. This is written immediately before firing the RPC. It acts as a bounded lock: any attempt that starts inside a specific validity window after an existing attempt marker is refused. I size that window to the 45 s ringing timeout plus the queue's acknowledgment budget. This guarantees that a genuinely in-flight attempt blocks a retry, while a dead attempt eventually releases the lock instead of wedging the phone number forever. En...

Powered by Readybot.io

**DEV Community** ## Task Queue Retry Called The Customer Twice …

DEV Community

Greenlight Counts Need a BigBlueButton Context Before They Mean Anything

Greenlight Counts Need a BigBlueButton Context Before They Mean Anything Greenlight is the end-user web interface for a BigBlueButton server. It handles accounts, rooms, meeting links, recordings, and the transition from a web session into a real-time conference. A ZoomEye count-only probe on November 15, 2026 returned 1 app="Greenlight" match, 1,108 title="Greenlight" matches, and 55,975 http.body="Greenlight" matches. The scope was sub_type=all, page 1, and page size 1. The title and body numbers are broad textual observations. "Greenlight" is a common word and appears in project names, marketing pages, and unrelated software. A single application fingerprint is a narrow signal, not a claim that only one Greenlight deployment exists. The useful next step is to establish whether a page belongs to a BigBlueButton frontend and what that frontend can control. The frontend is not the meeting server Greenlight and BigBlueButton can run on different hosts. The web interface may create a meeting and hand the user to a conference endpoint, while the media and recording services live elsewhere. Inventory both sides. A Greenlight login page without the associated BigBlueButton service is incomplete evidence, and a conference server without an identifiable frontend may still be reachable through a direct path. Review the BigBlueButton installation and Greenlight installation guides for the expected reverse proxy, TLS, and secret configuration. Confirm that the frontend uses the intended BigBlueButton host and secret. A test or staging frontend connected to a production conference server is a cross-environment authority problem. The application fingerprint can help separate a known Greenlight asset from generic title matches, but it should be combined with a response check. Use the page structure, login flow, and documented endpoints rather than inferring from the word alone. Account and room authority Greenlight can create local accounts and rooms. Public signup, guest join, room ownership, recordings, and administrative roles should be reviewed as separate permissions. A room link may be intended to be public. The administrator interface should not share that reachability. Test the invitation and join flow with an account that has the minimum expected role. Confirm that a user cannot change another room's settings or retrieve recordings outside the intended organization. Log room creation, role changes, and recording access with a bounded meeting identifier. Protect the BigBlueButton secret and any mail or single-sign-on credentials used by Greenlight. A web frontend that can create meetings may be less sensitive than the media server, but it can still disrupt classes, expose recordings, or send invitations to unintended recipients. Capacity and exposure The 55,975 body matches are far too broad to treat as a deployment population. They include the word in many contexts. The 1,108 title matches are still a discovery set. Filter by a verified Greenlight page, a BigBlueButton-related hostname, or a known deployment range before assigning ownership. Check whether a discovered host is a public demonstration, a documentation page, or a production portal. The official Greenlight project describes a free demo environment, so public examples are expected. A demo page should not be used as evidence that an organization's private meeting service is exposed. For confirmed services, measure availability and capacity separately from security. A reachable frontend that cannot create a meeting is not the same as a usable conferencing endpoint. A frontend that can create a meeting but cannot reach the media server may create a confusing outage without exposing conference data. What to record Record the Greenlight host, application evidence, related BigBlueButton host, TLS certificate, signup mode, guest join policy, recording retention path, and owner. Keep the ZoomEye observation timestamp and exact dorks with the evidence. Do not label title mat...

Powered by Readybot.io

**DEV Community** ## Greenlight Counts Need a BigBlueButton Context Before …

DEV Community

GitHub Actions reusable workflow input type mismatch

A GitHub Actions reusable workflow input type mismatch is the caller and the called workflow disagreeing about what a value is. workflow_call inputs are declared with a type and checked against it, so a quoted string sent to a boolean input, or an expression the typed key cannot accept, stops the run before any job starts. Three declared types, one list of contexts the with block accepts, and one cast for everything that arrives as text. What this error means One of two things happens, and they look nothing alike. The loud one is a validation failure in the caller: the run never starts, and the annotation names the input and the file it was not found in, or names the value it could not use. The quiet one is worse, because the run is green. A boolean input arrives holding text, the called workflow writes if: inputs.flag against it, and the condition is true whether the text says true or false, so a deploy that was supposed to be gated runs on every call. The tell for the quiet version is that toggling the caller changes nothing at all: the job runs identically with the flag set and cleared, and the only way to see it is to print the value rather than branch on it. ```Annotation, quoted from catalyst/catalyst-moodle-workflows#159 Invalid input, disable_phpcpd is not defined in the referenced workflow

Common causes

A quoted literal sent to a boolean or number input

YAML quoting decides the type before Actions sees it. publish: true is a boolean, publish: 'true' is a string, and the declared type is checked against what YAML produced. This is the version that passes validation in some shapes and then behaves as text inside the called workflow.

The value came from an expression, so it is text

Every step output is a string by definition, and a job output built from one is a string as well. Feeding it straight into a typed key gives you either a rejection or a truthy string, depending on where the mismatch lands. The cast has to be explicit because nothing casts it for you.

The with block reached for a context it is not allowed

Only six contexts are available in jobs.<job_id>.with.<with_id>. Referencing env, secrets or steps there produces an unrecognized name, and the typed key then rejects the whole value. Secrets have their own key, jobs.<job_id>.secrets, and that one does accept the secrets context.

The key is not declared in the called workflow at all

A rename on one side, a copied caller, or an input removed from a shared workflow. The parser is explicit about it, naming the key and the file: this is the one failure in the set that tells you precisely what to change.

How to fix it

Pass literals unquoted and let YAML carry the type

  1. Write true and false without quotes for a boolean input, and bare digits for a number.
  2. Keep quotes for strings, where they are harmless and sometimes necessary.
  3. Check the called workflow declares the type you think it does before changing the caller.

.github/workflows/ci.yml (illustrative) call: uses: ./.github/workflows/deploy.yml with: publish: true retries: 3 environment: 'staging' Cast expression results with fromJSON When the value comes from a step or a job output, wrap it. The cast belongs in the caller, at the moment the text becomes a typed input, and it keeps the called workflow honest about what it declared..github/workflows/ci.yml (illustrative) with: publish: ${{ fromJSON(needs.decide.outputs.publish) }} retries: ${{ fromJSON(needs.decide.outputs.retries) }}

Compare explicitly inside the called workflow

A condition that reads a bare input is only safe if the input really is a boolean. Comparing against the value you expect makes the job behave the same way whether the input arrived typed or as text, which is a useful property while a shared workflow has callers you do not control.

```.github/workflows/deploy.yml (illustrative)
jobs:
ship:
if: ${{ inputs.publish == t...

Powered by Readybot.io

**DEV Community** ## GitHub Actions reusable workflow input type mismatch …

DEV Community

How to get an EIN without an SSN or ITIN (Form SS-4 by fax or phone)

By OutsideFounder Team Originally published at https://outsidefounder.com/guides/ein-without-ssn. If you just formed a US LLC from abroad, the EIN is usually the next bottleneck. Banks, Stripe, and the IRS all want that nine-digit number, but the online EIN application expects a Social Security Number or ITIN. You do not need either of those. The IRS still issues EINs to foreign responsible parties for free, as long as you file Form SS-4 by fax or, in some cases, by phone. This is a practical walkthrough of the lines that matter, the correct fax numbers, realistic wait times, and what to do if the confirmation letter never arrives. It is general information, not tax or legal advice. Rules can change; confirm details on irs.gov. Facts below are current as of 15 November 2026. Short answer: On Form SS-4, enter Foreign (or N/A) on line 7b. If the LLC has no US place of business, fax 304-707-9471 from outside the US, or 855-215-1627 from inside the US. If you listed a US street address as the place of business, fax 855-641-6935 instead. International applicants with no US place of business can also call 267-941-1099. There is no IRS fee. The IRS says fax applications take about 4 business days; founders often report 1–6 weeks. Key facts Item Value Source IRS fee for an EIN Free IRS – Instructions for Form SS-4 Fax, no US place of business (from outside the US) 304-707-9471 IRS – Instructions for Form SS-4 Fax, no US place of business (from within the US) 855-215-1627 IRS – Instructions for Form SS-4 Fax, US place of business 855-641-6935 IRS – Instructions for Form SS-4 Phone, international applicants 267-941-1099 (Mon–Fri, 6 a.m.–11 p.m. Eastern) IRS – Instructions for Form SS-4 IRS-stated time by fax About 4 business days IRS – Instructions for Form SS-4 Before you start The LLC must already exist: you need approved Articles of Organization. Have the exact legal name, the formation date, and a mailing address ready. Choose the responsible party: the individual who ultimately owns or controls the LLC, usually you. You need a fax number that can receive a reply. An online fax service is fine. If you are still deciding whether an ITIN is required later, see our separate EIN vs ITIN guide for non-residents. An ITIN is not a prerequisite for this EIN application. Filling in Form SS-4: the lines that trip people up Download the current revision from irs.gov/FormSS4. Line What to enter 1 The LLC's exact legal name, as on your Articles. 4a–4b / 5a–5b Mailing address, and the physical street address only if it is different (no P.O. box on 5a). For an address outside the US, write out the country name. The address you give affects routing. The international fax and phone numbers are for entities with no legal residence, principal place of business, or principal office in the US. A US street address as the LLC's physical location points you to the domestic fax 855-641-6935 instead. 7a–7b Responsible party's name. On 7b enter Foreign or N/A if they do not have, and are not eligible for, an SSN or ITIN. An entry is required. 8a–8c Yes, it is an LLC; number of members; formed in the US. 9a Single-member, foreign-owned: check Other and write Foreign-owned U.S. disregarded entity-Form 5472 (the IRS wording). Multi-member: Partnership, unless you elect otherwise. 10 Foreign-owned single-member LLC: check Other and write Foreign-owned U.S. disregarded entity filing Form 5472 (the IRS wording). Otherwise, use the reason that applies (for example "Started new business"). Signature Sign, date, and add your phone and fax number so the IRS can fax the EIN back. Those Form 5472 labels on lines 9a and 10 are about how the IRS classifies a foreign-owned disregarded LLC. They do not file the annual Form 5472 for you; that is a separate yearly filing. Three ways to apply Fax (most common) The IRS chooses the fax number from the entity's location on lines 4a/5a. No legal residence, principal place of business, or principal office or agency in a US state...

Powered by Readybot.io

**DEV Community** ## How to get an EIN without an …

DEV Community

🖥️ Remote Desktop Can't Connect? Check These 3 Things Before You Reboot

"I can't RDP into my machine." 😩 Every help desk hears this one. The tempting fix is to ask someone to reboot the PC and hope. But most RDP failures come down to just three things: can you reach it, is RDP on, and is the user allowed in? Check them in order and you'll usually have the answer in minutes. ⚡ 🌐 1. Can you even reach it? Before anything else, test the RDP port (3389) from the computer you're connecting from: Test-NetConnection -Port 3389
Look at the last lines: TcpTestSucceeded : True ✅ The network path is fine. Move on to step 2. TcpTestSucceeded : False ❌ Something is in the way. If it fails, narrow it down: Resolve-DnsName # Does the name resolve to the right IP?
ping # Is the PC even awake?
Common causes: wrong or stale DNS record, VPN not connected, Windows Firewall blocking Remote Desktop, or the PC is asleep or powered off. ⚙️ 2. Is Remote Desktop turned on? On the target PC: Settings > System > Remote Desktop > Remote Desktop = On Two gotchas here: 🚫 Windows Home editions can't host RDP. You can connect from Home, but not to it. Check with: (Get-CimInstance Win32_OperatingSystem).Caption
🔥 Turning RDP on through Settings normally opens the firewall rule too. If someone enabled it another way, confirm the "Remote Desktop" firewall rules are enabled. 👤 3. Is the user allowed in? If the port is open and RDP is on, but sign-in says the user isn't authorized, it's permissions. The user must be a local admin or a member of the Remote Desktop Users group on that PC: net localgroup "Remote Desktop Users"
To add someone (elevated prompt): net localgroup "Remote Desktop Users" "DOMAIN\username" /add
In many organizations this is controlled by Group Policy, so a manual add might get reverted. In that case, follow your team's process for requesting access. 🎯 The quick recap 1️⃣ Port – Test-NetConnection -Port 3389 2️⃣ Setting – Remote Desktop On (and not a Home edition) 3️⃣ Permission – user in Remote Desktop Users or local admins Work through them in that order and you'll know where it's broken before you touch anything. 🧠 What's your first move when an RDP ticket lands? Drop it below 👇

Powered by Readybot.io

**DEV Community** ## 🖥️ Remote Desktop Can't Connect? Check These …

DEV Community

The EDI 180, Decoded: A Return Is a Negotiation, Not a Credit Memo

What is the EDI 180? The EDI 180 (Return Merchandise Authorization and Notification) is the X12 transaction a buyer uses to ask a seller for permission to send goods back — and the message the seller answers with. Short answer: an 180 is not a credit memo and it is not a shipment. It is a negotiation, in a standard format, about what may come back, in what condition, and who pays for the trip. That distinction is where most returns integrations go wrong. Teams model a return as a negative order. It isn't. An order is an instruction; a return starts as a request, and until the seller authorizes it, nothing should move. Why does a return need authorization at all? Because the seller has questions the buyer cannot answer for them. Is the item resalable, or is it damaged? Is it inside the return window? Should it go back to the distribution center, to a refurbisher, or nowhere at all — sometimes the cheapest correct answer is "keep it, credit issued." The 180 carries the buyer's side of that conversation: which items, how many, what condition, and why. The reason codes are the heart of it. A return because the buyer over-ordered is a different financial event from a return because the product arrived defective, and both differ from a recall. If your integration collapses every return into one generic bucket, your partner's deductions team will happily reclassify them for you — at their rates, on their timeline. What does an 180 actually contain? At the header level, the transaction identifies the return authorization request itself: who is asking, which seller location or returns center is involved, and the references that tie the return back to the original business — the original purchase order, the original invoice, and the shipment the goods arrived on. Lose those references and the seller is matching cartons to orders by hand, which is exactly the labor the standard exists to eliminate. At the line level, each item states the product identifier (usually the same UPC or buyer part number used on the original 850), the quantity proposed for return, the condition, and the reason. Quantities deserve care: the quantity requested, the quantity authorized, and the quantity actually received back are three different numbers, and a healthy returns flow tracks all three instead of overwriting one field. The seller's response can authorize all, part, or none of the request, and can direct disposition — return to stock, repair, scrap in field, or hold for inspection. That partial-authorization case is the one homegrown integrations most often forget to build. How does the 180 fit with the rest of the returns flow? The 180 does not travel alone. The physical return shipment is usually announced with an 856 (Advance Ship Notice) so the receiving dock knows what is coming and can match cartons against the authorization. Money settles later: an 812 (Credit/Debit Adjustment) or the credit side of an 810 handles the financial correction once the goods are received and inspected. The acknowledgment discipline is the same as everywhere else in X12 — a 997 confirms the 180 arrived and parsed, not that anyone agreed to anything. Sequencing matters. If the credit is issued when the 180 is requested rather than when the goods are received and inspected, you have built a machine for giving away product. If the 856 for the return references no authorization number, the dock cannot tell an approved return from a random box, and random boxes sit. Every returns dispute I have seen traces back to one of those two sequencing mistakes. What breaks most often in 180 integrations? Three things. First, condition and reason codes mapped loosely — your partner's guide enumerates the values they accept, and sending a plausible-but-unlisted code gets the line rejected or, worse, silently reclassified. Second, identifiers that drift from the original order: if the 850 said one part number and the 180 says another, matching fails. Third, treating the authorizati...

Powered by Readybot.io

**DEV Community** ## The EDI 180, Decoded: A Return Is …

DEV Community

ncipollo/release-action 403 on release create

A ncipollo/release-action 403 on release create means the releases API received a token and declined to act on it, which is a different failure from having no token at all. The number in front of the colon is the whole diagnosis, and the action prints it for exactly that reason. The action prints GitHub's status and GitHub's sentence. Only the 404 branch appends a sentence of its own: "Make sure your github token has access to the repo and has permission to author releases". What this error means The build steps are green and the release step is red. The line is short: the word Error, a three digit status, a colon, and a sentence that came from GitHub rather than from the action. Nothing in it names an input, a secret or a permission, so the workflow file gets edited on a guess. A 403 and a 401 look almost identical in the log and mean opposite things about your token, and a 404 arrives with one extra sentence that the other two do not have. ```Actions log, quoted from a public pull request listed in the references Run ncipollo/release-action@v1 Error 403: Resource not accessible by integration [error]Error 403: Resource not accessible by integration

Common causes

The job has a read-only token and the step is a write

The 403 case. The default permissions for GITHUB_TOKEN are read-only in most organizations created recently, and creating a release is a write to repository contents. Nothing in the step declares that need, so the first time the job asks, it is refused.

The token input was overridden with something empty

The 401 case. A step that passes token: ${{ secrets.RELEASE_TOKEN }} with no such secret sends an empty string, which replaces the working default. The action does not check, so github.getOctokit("") builds an unauthenticated client and the API answers 401 rather than naming the input.

The release is being created in a repository the token cannot see

The 404 case, which the extra remediation sentence identifies. It happens with the owner and repo inputs pointed at a second repository, and with a token whose reach stops at the repository running the workflow. A private repository the token cannot see returns 404 rather than 403 by design.

An organization policy overrides a correct permissions block

Worth ruling out last, because the block looks right. An organization or enterprise can cap what a workflow may request, and a job asking for contents: write under such a policy still runs with less. The job setup summary lists what was granted, which is the only place the two differ visibly.

How to fix it

Read the status before changing anything

  1. Find the line beginning Error in the release step and note the three digit number.
  2. If a second sentence follows about the token having access to the repo, the status was 404 and the repository is the problem, not the permission.
  3. If there is no second sentence, a 403 means the token was refused and a 401 means it was never sent.

Grant contents: write for the 403

The permission belongs on the job that creates the release, not on the workflow, so the other jobs keep the read-only default. This is the whole repair for the common case.

```.github/workflows/release.yml (illustrative)
jobs:
release:
runs-on: ubuntu-latest
permissions:
contents: write
steps:
- uses: actions/checkout@v5
- uses: ncipollo/release-action@v1
with:
tag: ${{ github.ref_name }}
Stop overriding the token, or make the override real For the 401, delete the token input and let the declared default apply. Keep it only when the release must be authored by something other than the workflow's own identity, and then confirm the secret exists at the scope the job runs in. An organization secret not shared with this repository resolves to an empty string in exactly the same way a misspelled name does. Point owner and repo at a repository the credential can reach For the 404, either drop the owner ...

Powered by Readybot.io

**DEV Community** ## ncipollo/release-action 403 on release create A ncipollo/release-action …

DEV Community

AI Concept Renders Are Not Technical Drawings: A Practical Quality-Control Workflow

Disclosure: I develop Estate Render, an AI-assisted visualization tool mentioned at the end of this article. This is a practical workflow article, not a construction or engineering standard. A generated interior image can be striking and still be wrong for a real project. An additional window might appear. A cabinet might change width. The camera might shift just enough to make two material options impossible to compare fairly. For people building tools around generative images, this is an important product-design problem: a convincing output is not necessarily a faithful output. The solution is not to pretend that a concept render is a measured drawing. It is to give the user a simple, repeatable way to review what changed, what must not change, and which decisions still need verification. 1. Define the source of truth before generating Every rendering workflow needs an explicit source of truth. Depending on the task, it may be a SketchUp screenshot, a photograph of an existing room, or a moodboard. Those inputs do different jobs: Model screenshot: communicates spatial intent and a camera view, but may lack complete material or construction information. Existing-room photograph: records visible conditions, but can conceal measurements and areas outside the frame. Moodboard: describes desired visual direction; it does not define a room's geometry. A good UI should make that distinction apparent. Don't let users accidentally treat a moodboard as a floor plan or a generated image as a measurement. A simple pre-render form can ask three questions: What is the starting image? What may change? What must stay the same? Even when this information does not control a model perfectly, it improves the subsequent review. 2. Separate fixed constraints from creative variables When a designer wants to compare finishes, they should not have to compare different room layouts at the same time. Consider this design brief: Fixed: camera position, wall openings, visible room proportions, major built-in furniture, and circulation path. Variable: wall color, floor finish, loose furniture palette, lighting temperature, and decorative objects. That distinction makes a series of images more useful. If one alternative quietly moves a doorway, the comparison is no longer like-for-like. From a product perspective, it is worth making the two lists visible next to each generated output. They serve as a human-readable audit trail, even if the underlying generation service is probabilistic. 3. Build a review checklist instead of a confidence score It is tempting to expose a single “quality: 92%” metric. But what would that mean? The image might look photorealistic while displaying the wrong geometry. A more honest approach is a checklist users can verify: Check Reviewer question Result Layout Are visible walls and major openings preserved? Pass / Review Scale Do furniture and circulation still look plausible? Pass / Review Materials Does each chosen finish appear where intended? Pass / Review Camera Is the viewpoint consistent across alternatives? Pass / Review Lighting Are changes intentional rather than accidental? Pass / Review Deliverable Is the image clearly labeled as a concept? Pass / Review This checklist is deliberately qualitative. Some problems require source measurements, technical documentation, or a qualified professional. A screenshot alone cannot validate building-code compliance or exact dimensions. 4. Make the review state explicit in software A small amount of structured data goes a long way. For instance, a frontend can track review status separately from the output image: const conceptReview = {
sourceType: "sketchup-screenshot",
intendedChanges: ["floor finish", "lighting mood"],
fixedElements: ["window positions", "cabinet layout"],
checks: {
geometry: "review",
materials: "pass",
camera: "pass",
lighting: "review",
conceptLabel: "pass"
},
approvedFor: "client-discussion-only"
};

const needsReview = ...

Powered by Readybot.io

**DEV Community** ## AI Concept Renders Are Not Technical Drawings: …

DEV Community

How to use Mosh on Mac and iPhone, and keep sessions alive with tmux

SSH drops the moment your laptop sleeps, your train goes into a tunnel or your iPhone switches from Wi-Fi to 5G. Mosh fixes the connection part. tmux fixes the "my job died with it" part. Together they make a remote shell you can close and reopen from anywhere. This guide sets up both on a Linux server and shows how to connect from a Mac and from an iPhone. The short answer # on the server
sudo apt install mosh tmux # Debian / Ubuntu
sudo ufw allow 60000:61000/udp # only if ufw is on

on the Mac

brew install mosh
mosh user@your-server -- tmux new -A -s main
tmux new -A -s main attaches to the session called main if it exists, or creates it. Run the same command again tomorrow and you are back where you left off. What Mosh does, and what it does not Mosh (mobile shell) logs in over SSH, starts mosh-server on the remote machine, and then talks to it over UDP. Because the session is not tied to one TCP connection: it survives a change of IP address (Wi-Fi to cellular, home to office); it survives the laptop sleeping or the iPhone locking; it shows what you type right away, even on a slow link, instead of waiting for the server's echo. What it does not do: keep your programs running if the server side of the session ends, scroll back through history the way your terminal does, or forward ports. For the first two, you add tmux. Install on the server Debian and Ubuntu: sudo apt update
sudo apt install mosh tmux
Fedora, RHEL and friends: sudo dnf install mosh tmux
Mosh uses one UDP port per session in the range 60000 to 61000. If a firewall is on, open it: sudo ufw allow 60000:61000/udp
On a cloud server, add the same range as an inbound UDP rule in the provider's firewall too. Mosh also needs a UTF-8 locale on the server. If you get an error about LANG or LC_ALL, this usually fixes it: sudo locale-gen en_US.UTF-8
Connect from a Mac Install the client with Homebrew and connect the same way you would with SSH: brew install mosh
mosh user@your-server
If SSH runs on another port, pass the SSH command through: mosh --ssh="ssh -p 2222" user@your-server
Your ~/.ssh/config is used as usual, so a host alias works too: mosh myserver. Add tmux so the work survives Mosh keeps the connection alive. tmux keeps the programs alive, even if you close the Mosh session on purpose or the server reboots your login. Start or reattach in one step: mosh myserver -- tmux new -A -s main
The keys you need on day one: Keys What it does Ctrl-b d detach: leave everything running and disconnect Ctrl-b c new window Ctrl-b n / Ctrl-b p next / previous window Ctrl-b % split side by side Ctrl-b [ scroll back (press q to leave) Later, from any device: tmux ls # list sessions
tmux attach -t main # go back in
This is the setup many people use to leave a long build, a database migration or an AI coding agent such as Claude Code or Codex running on a server and check on it from the phone. Connect from an iPhone or iPad iOS has no built-in terminal, so you need an SSH app that supports Mosh. Look for three things: Mosh support, not only SSH, so the session survives the phone locking; key handling you trust, ideally keys that never leave the device; a way to reattach to your tmux session without typing the command every time. The flow is the same as on the Mac: connect with Mosh, then tmux new -A -s main. We make Wardterm, an SSH client for Mac, iPhone and iPad, and we built it around this exact workflow. Mosh is included on every device, and Keep This Session moves the current session into tmux on the server for you, so you can close the app and pick it up later from the Mac or the phone. If you run AI agents on the server, it also tells you when one is waiting for an answer. The free plan has no limit on servers: https://wardterm.com/ Troubleshooting "mosh-server: command not found" Mosh is not installed on the server, or not on the PATH of a non-interactive SSH login. Install it, or point to it: mosh --server=/usr/local/...

Powered by Readybot.io

**DEV Community** ## How to use Mosh on Mac and …

DEV Community

GitHub Actions run-name env not available, and what it can read

GitHub Actions run-name env not available is a workflow that fails to compile rather than a run that gets a blank name. The key carries a short list of allowed contexts, env is not on it, and an expression naming a context outside the list is rejected while the file is being read. The run name is decided before any job exists, so only the event, the dispatch inputs and repository variables are reachable from it. What this error means You added an environment variable to the run name, expecting either the value or an empty string, and instead the workflow stopped running entirely. The annotation is on the file and quotes a name rather than a value. A second, milder version exists where the run name shows literal braces instead of a value, and that one has a different cause: the expression was never treated as an expression, usually because of how it was quoted. ```Message composed by ParseException in actions/runner, with the file and line prefix The workflow is not valid. .github/workflows/deploy.yml (Line: 4, Col: 11): Unrecognized named-value: 'env'. Located at position 1 within expression: env.TARGET

Common causes

The run name referenced a workflow level env value

The commonest one, and it looks reasonable because the env: block is a few lines below in the same file. Proximity in the file is not availability in the expression: the key's context list decides, and env is not on it.

The value was expected to come from a step

A version number computed during the build cannot appear in the run name, because the name is decided before any step runs. No context would help, since the value does not exist at that moment.

The expression was written but never parsed as one

This is the variant that produces a literal pair of braces in the name rather than an error. It comes from quoting or escaping that stops the reader recognizing an interpolation, which means nothing was rejected because nothing was parsed.

A repository variable was assumed to be unavailable

The documentation sentence names github and inputs only, so people conclude vars is out and reach for env instead. The schema's context list for the key includes vars, which makes a repository variable the closest thing to a workflow level default that a run name can read.

How to fix it

Use a repository variable instead of a workflow env value

Move the value to a repository or organization variable and read it through vars, which is on the key's context list. This is the nearest equivalent to a workflow level default that survives being read before any job exists.

.github/workflows/deploy.yml (illustrative) run-name: Deploy ${{ vars.DEPLOY_TARGET }} from ${{ github.ref_name }} Take the value as a dispatch input Declare the input under on.workflow_dispatch.inputs with a type and a default. Read it in run-name through the inputs context. Give the input a description, because it now appears in the run name and people will read it as a label. Keep the same input available to the jobs, so the name and the behavior cannot drift apart. Put a computed value on the job or in the summary For anything a step produces, name the job with what is known at job level and write the computed detail to the step summary. The summary is rendered on the run page, which is the surface most people are actually trying to improve when they reach for a dynamic run name..github/workflows/deploy.yml (illustrative) run: echo "### Deployed ${VERSION}" >> "$GITHUB_STEP_SUMMARY" ``` Drop the key and take the default name When there is nothing available worth putting in it, leave run-name out. The documentation records that an omitted or whitespace-only value produces event specific information instead, which for a push is the commit message and for a pull request is its title, and both are usually more informative than a static string. How to prevent it Check a key's context list before writing an expression into it. Keep values that belong in a run name a...

Powered by Readybot.io

**DEV Community** ## GitHub Actions run-name env not available, and …

DEV Community

Should you block AI crawlers (GPTBot, ClaudeBot, CCBot) in robots.txt? Let's argue about it

Automated technical SEO checks that catch indexing blocks and deploy regressions — seotto.com A couple of years ago, robots.txt was mostly about search engines. Now a typical site's logs include a whole list of AI-related crawlers: OpenAI's, Anthropic's, Common Crawl's, Perplexity's, Apple's, ByteDance's and others. Many sites added blanket blocks in a hurry. Others never touched their robots.txt. Should you block them? I think this is a genuinely open question, and the answer has changed as the bots themselves have changed. Let's argue about it. First, they're not all the same bot The big operators now publish several user agents with different purposes. Roughly: Training crawlers collect pages to train models: for example OpenAI's GPTBot, Anthropic's ClaudeBot, Common Crawl's CCBot (used by many model builders). Search crawlers index pages so an AI product can cite and link to them in answers: for example OAI-SearchBot, PerplexityBot, Claude-SearchBot. User-triggered fetchers load a page because a person asked the assistant to read it right now: for example ChatGPT-User, Claude-User. Control tokens that aren't crawlers at all: Google-Extended and Applebot-Extended are names you can disallow in robots.txt to opt out of your content being used for those companies' AI models, without affecting Google Search or Apple's search features. Names and purposes change, so check each operator's current documentation before relying on a list. The point is that "block AI" now means several separate decisions. The case for blocking Consent. Your content was written for readers, and nobody asked whether it could be used to train a commercial model. Blocking training crawlers is the clearest signal you can give. No traffic in return. Training a model on your article doesn't send anyone to your site. If the model can then answer the question your article answers, it may reduce your traffic. Server cost. Some AI crawlers are aggressive, request huge numbers of pages, and ignore crawl-delay hints. Smaller sites have seen real bandwidth and CPU costs from them. Leverage. Publishers negotiating licensing deals have argued that blocking is the only bargaining position content owners have. The case for allowing AI answers are a discovery channel now. People ask assistants for recommendations, documentation and comparisons. Products that cite sources can only cite pages their search crawlers can read. Block the search agents and you're invisible there. Developer content wants to be found. For documentation, open source projects and developer tools, being the source an assistant learned from, or cites, is often the whole point of publishing. Blocking doesn't remove what's already collected. Pages crawled before you added the rule may already be in datasets. A new block only affects future crawling. robots.txt is voluntary. Well-behaved crawlers follow it. Badly behaved ones don't, and some scrapers simply pretend to be a browser. A block mostly affects the operators who were already playing fair. Before you tighten robots.txt, it helps to see what is already blocked. seotto.com checks for indexing blocks and robots regressions, including rules you didn't mean to ship. Where I've landed For most sites, I'd make the decision per purpose, not per company: User-triggered fetchers: allow. A person asked an assistant to read your page. That's closer to a browser visit than to crawling, and blocking it mainly frustrates your own readers. AI search crawlers: allow, if being cited matters to you. For most commercial and developer sites, it does. Check your logs and analytics for referrals from AI products before deciding. Training crawlers: a values decision. There's no technical right answer. Blocking GPTBot, ClaudeBot, CCBot and setting Google-Extended and Applebot-Extended to disallow is a coherent position; so is allowing them. Decide deliberately and write down why. Aggressive crawlers: rate limit, don't just disallow. If one bot is costing you real ...

Powered by Readybot.io

**DEV Community** ## Should you block AI crawlers (GPTBot, ClaudeBot, …

DEV Community

Image Upload Moderation: Retaining NSFW Evidence with JSON Schema Fallback

Image Upload Moderation: Retaining NSFW Evidence with JSON Schema Fallback For catalog image upload moderation, classify NSFW content and violence before publishing enrichment, and retain the evidence for an explicit review window. The bill has several parts: image bytes held over time, classification attempts, review work, and the reads and writes needed to move evidence through those decisions. Keeping every upload indefinitely is a storage policy, even when nobody remembers choosing it. Consider a deliberately hypothetical B2B SaaS catalog: 10,000 uploads per day, each normalized image exactly 1 MB, with one retained image per upload. In decimal units, that adds 10 GB per day; a 30-day window holds 300 GB at steady state, while a 7-day window holds 70 GB. The 230 GB difference is arithmetic, not a production measurement or a claim about a storage service. Image bytes dominate the retained data in this example if each decision record is capped at 1 KB: those records add only 10 MB per day. This says nothing about which charge dominates the total invoice; model usage and human review need their own measurements. Short answer: for a Node.js image upload moderation flow, classify NSFW content, violence, and hate symbols through multimodal chat, validate the result against a JSON Schema contract, and route malformed or uncertain answers to a bounded fallback or review. For catalog enrichment, the quality-versus-latency choice belongs at publication: a fast upload acknowledgment can coexist with a slower, evidence-backed decision before extracted attributes become visible. The examples below use Python to make that boundary inspectable independently of the upload server. Keep evidence bounded. How should image upload moderation retain NSFW and violence evidence? A messy description such as “vintage patch, black/red, collectible, maybe military” is a useful illustrative input because enrichment and moderation ask different questions. Enrichment might infer color or product type; moderation must decide whether the associated image can enter the published catalog under the service's policy. Neither task should treat the seller's description as an instruction, and the text alone should not settle what an ambiguous emblem means. Preserve uncertainty instead of converting a seller's confident wording into a confident classification. The storage boundary matters more than a polished response example. Give each upload an immutable identifier and associate the decision with the exact image version inspected, the relevant description version, the policy version, and the classifier configuration. Treat this as a proposed application contract: if any input changes, the previous decision is ineligible to authorize publication of the replacement. An image digest helps identify byte equality; it does not recover deleted pixels or explain the model's judgment. Store the normalized classifier input as the review evidence when review requires replaying that input. If the original is also retained, account for it separately: the opening calculation explicitly excludes originals, thumbnails, replicas, and old versions. Deleting one database row is not a complete retention implementation when the image has other copies with different lifetimes. That omission is easy to miss. The compact record should carry the upload identifier, evidence digest, three labels, uncertainty, policy and schema versions, decision state, evidence expiration time, and a reason code. It should also say when evidence has been deleted. A surviving record can establish which policy decision was recorded; without the image, it cannot support a fresh visual assessment. Those are different audit capabilities, and a retention discussion that bundles them together conceals the actual loss. Typed labels keep enrichment behind a publication boundary Use a small contract whose meaning the application owns. For this illustrative policy, each of nsfw, violence, and hate_symbols is pr...

Powered by Readybot.io

**DEV Community** ## Image Upload Moderation: Retaining NSFW Evidence with …

DEV Community

How to measure how much of your crawl traffic is AI bots, from your own access logs (in Python)

Automated technical SEO checks that catch indexing blocks and deploy regressions — seotto.com Opinions about AI crawlers are everywhere. Numbers from your own site are rarer, and they're the only ones that should drive a robots.txt change. The questions worth answering first: What share of all bot requests come from AI-related crawlers? How much bandwidth do they use? Which sections of the site do they hit? Are they training crawlers, search crawlers, or fetches triggered by a person asking an assistant to read your page? Your access logs already have the answers. This post is a short Python script that classifies requests by user agent and reports exactly those numbers. The categories User agent strings change, and operators add new ones, so treat this as a starting list and check each operator's documentation before relying on it: Search crawlers: Googlebot, bingbot, DuckDuckBot, YandexBot, Applebot (the plain one, used for Apple's search features). AI training: GPTBot, ClaudeBot, CCBot, Bytespider, meta-externalagent, Amazonbot, cohere-ai. AI search: OAI-SearchBot, PerplexityBot, Claude-SearchBot. AI user-triggered: ChatGPT-User, Claude-User, Perplexity-User. Google-Extended and Applebot-Extended won't appear in logs: they're robots.txt tokens, not separate crawlers. Google's AI products fetch with the normal Googlebot. Like Googlebot, all of these can be faked. A request claiming to be GPTBot from a residential IP is probably a scraper. The bigger operators publish their IP ranges; for numbers you'll act on, check requests against those ranges, the same way you'd verify Googlebot with reverse DNS. The script import gzip, glob, re, sys
from collections import Counter, defaultdict

CATEGORIES = {
"search": ["Googlebot", "bingbot", "DuckDuckBot", "YandexBot", "Applebot/"],
"ai-training": ["GPTBot", "ClaudeBot", "CCBot", "Bytespider", "meta-externalagent",
"Amazonbot", "cohere-ai"],
"ai-search": ["OAI-SearchBot", "PerplexityBot", "Claude-SearchBot"],
"ai-user": ["ChatGPT-User", "Claude-User", "Perplexity-User"],
}
BOTLIKE = re.compile(r"bot|crawl|spider|slurp|fetch", re.I)

combined log format: ... "GET /path HTTP/1.1" 200 1234 "referer" "user agent"

LINE = re.compile(r'"[A-Z]+ (\S+) [^"]" (\d{3}) (\d+|-) "[^"]" "([^"]*)"')

def classify(ua):
for cat, needles in CATEGORIES.items():
for n in needles:
if n in ua:
return cat, n
if BOTLIKE.search(ua):
return "other-bot", "other"
return "human/other", "-"

def lines(pattern):
for p in sorted(glob.glob(pattern)):
f = gzip.open(p, "rt", errors="replace") if p.endswith(".gz") else open(p, errors="replace")
with f:
yield from f

reqs, bytes_, agents = Counter(), Counter(), Counter()
paths = defaultdict(Counter)
statuses = defaultdict(Counter)
for line in lines(sys.argv[1]):
m = LINE.search(line)
if not m:
continue
path, status, size, ua = m.groups()
cat, agent = classify(ua)
reqs[cat] += 1
bytes_[cat] += 0 if size == "-" else int(size)
agents[(cat, agent)] += 1
section = "/" + path.lstrip("/").split("/", 1)[0].split("?", 1)[0]
paths[cat][section] += 1
statuses[cat][status[0] + "xx"] += 1

total_bot = sum(n for c, n in reqs.items() if c != "human/other")
print(f"{'category':14s} {'requests':>10s} {'% of bots':>10s} {'MB':>10s} statuses")
for cat, n in reqs.most_common():
share = "" if cat == "human/other" else f"{100 * n / max(total_bot, 1):.1f}%"
print(f"{cat:14s} {n:10d} {share:>10s} {bytes_[cat] / 1e6:10.1f} {dict(statuses[cat])}")

print("\nTop agents:")
for (cat, agent), n in agents.most_common(15):
if cat != "human/other":
print(f"{n:8d} {cat:12s} {agent}")

for cat in ("ai-training", "ai-search", "ai-user"):
if paths[cat]:
print(f"\nTop sections for {cat}:")
for s, n in paths[cat].most_common(8):
print(f"{n:8d} {s}")
Run i...

Powered by Readybot.io

**DEV Community** ## How to measure how much of your …

DEV Community

PWC 399

This week's tasks are about length, so let's cue up the Eagles Long Run album from 1979 and get to work. Task 1: Longest Repeating Character Task Description You are given a string str and an integer k > 0. Write a script to choose any character of str and change it to another character. You may perform this operation up to k times. Return the length of the longest reachable substring of a single letter. Example 1: Input: $str = "AAAAA", $k = 2 Output: 5 Every character in the string is already the same letter "A". The maximum operations allowed (k = 2) do not even need to be used. The entire string of length 5 is already the longest valid substring. Example 2: Input: $str = "ABCDE", $k = 4 Output: 5 All 5 characters in the string are distinct. The most frequent character occurs only 1 time. To turn the entire string into a single repeated character, we need to replace 5 - 1 = 4 characters. Since k = 4, we can replace "B","C","D", and "E" with "A" to form "AAAAA". Example 3: Input: $str = "AAABBBBAA", $k = 1Output:5 If we target "A", we could change the "B" in "AAAB" (k=1 replacement) to get length 4 ("AAAA"). If we target "B", we can pick the substring "BBBBA" and change the single trailing "A" to "B" (k=1 replacement) to form "BBBBB", which gives a length of 5. Targeting "B" gives better result than targeting "A". Example 4: Input: $str = "ABACADA", $k = 2 Output: 5 Look at the substring [0..4] which is "ABACA" (length 5). In this window, "A" appears 3 times, and there are 2 non-"A" characters ("B" and "C"). With k = 2, we can replace "B" and "C" with "A" to form "AAAAA". Look at the substring [2..6] which is "ACADA" (length 5). Here, "A" appears 3 times, and non-"A" characters ("C" and "D") count to 2. Replacing them gives "AAAAA". In both cases, the maximum valid length is 5. Example 5: Input: $str = "BAAABAAAA", $k = 1 Output: 8 The string has two groups of "A"s separated by a single "B" ("AAABAAAA"). We can replace the character 4 "B" with an "A" to get a sequence of 8 "A". The thought process There seem to be a lot of combinations to work through. Something easier would be to take every character in turn and see how long of a streak we can make of that character. There's no prize being awarded for being frugal with substitutions, so let's just do k substitutions every time and see where we land. Some code sub task($str, $k)
{
my $longest = 1;
my $strlen;
while ( ($strlen = length($str)) > 0 && $strlen > $longest )
{
# Shift left-most character off str
my $c = substr($str, 0, 1, "");

    # Make as many substitutions as possible
    my $copy = $str;
    $copy =~ s/[^$c]/$c/ for 1 .. $k;

    # Check the length of repeated first character
    $copy =~ m/^($c+)/;
    my $run = 1 + length($1 // "");

    $longest = $run if $run > $longest;
}
return $longest;

}
The body of the loop is to consider the first character of the string, chop it off, and continue until the string is empty or we can't beat the longest value. The four-argument version of substr simplifies it for us -- it returns the first character, and the fourth argument effectively removes it by replacing it with an empty string. We want to modify the string, so we'll operate on a copy. In the copy, we substitute the first k characters that aren't $c. We may end up doing too much in this step, but, meh. To check the length, do a regular expression match for repetitions of $c at the beginning of $copy. Capture the match and check its length. The +1 is there to account for $c. Task 2: Longest Absolute Path Task Description You are given a filesystem as string. Write a script to return the length of the longest absolute path to a file in the abstracted file system. If there is no file in the system, return 0. dir
- subdir1
- file1.ext
- subsubdir1
- subdir2
- subsubdir2
- file2.ext
The above filesystem can be represented as below: "dir\n\tsubdir1\n\t\tfile1.ext\n\t\tsubsubdir1\n\t...

Powered by Readybot.io

**DEV Community** ## PWC 399 This week's tasks are about …

DEV Community

A five-minute triage for remote-desktop lag

Remote desktop sessions that "feel slow" usually fail on one of three things, and each has a different fix. Before opening a ticket about bandwidth, spend five minutes on this order. 1. Is it input latency or render latency? Type in a local text field, then type in the remote one. If the characters appear late but arrive in a burst, the problem is the path (latency + jitter). If they appear smoothly but the screen redraws slowly, the problem is encoding or the remote GPU. These look similar on a video call and are completely different problems. 2. Measure the path, not the speed A speed test measures throughput to a nearby server and tells you almost nothing about a cross-region session. You want round-trip time, loss and jitter to the actual destination: mtr -rwzbc 100
Read it top to bottom. The first hop where loss stays flat and latency jumps is the segment to avoid. Anything under ~0.5% loss is usually absorbed by TCP; above 1% you feel it as stalls. 3. Check whether the session survives a route change If a route switch resets the TCP connection, every switch is a visible freeze, and the client will look worse than a static path. A session-preserving switch - moving packets to a better path without tearing down the socket - is what turns an unstable link into a usable one. This is the part a cross-border network acceleration client is responsible for; the measurement is the easy half. 4. Only then look at bandwidth Bandwidth matters for file transfer and video, not for typing. If your session is unusable at 5 Mbps but the link shows 100 Mbps idle, bandwidth was never the bottleneck. The short version Input lag in bursts -> path (latency/jitter/loss) -> measure with mtr. Smooth input, slow redraw -> encoding/GPU -> check codec and resolution. Freeze on every route change -> the client, not the network. Most "slow remote desktop" reports I see resolve at step 2, and the ones that do not are usually step 3 wearing a disguise.

Powered by Readybot.io

**DEV Community** ## A five-minute triage for remote-desktop lag Remote …

DEV Community

Context rot: why your AI assistant gets worse after 200 messages (and a 5-line fix)

You've seen it. The first hour with an AI assistant is great. By message 200 it suggests a fix you already rejected, forgets the framework you're using, and confidently reintroduces a bug from an hour ago. That's context rot, and it's not your imagination. What's going on Every model has a limited context window. Long chats fill it with everything: dead ends, abandoned approaches, old versions of the same file. Even when it all technically fits, the model has to decide what matters, and old noise competes with the new signal. Common symptoms: it repeats suggestions you already turned down; it mixes up two versions of the same function; it drifts away from the original goal; answers get longer and vaguer. The fix: a 5-line handoff When you notice the symptoms, stop. Ask the model: Summarize this conversation in 5 lines: goal, constraints, decisions made, current state, next step. Check the summary, fix anything wrong, then start a new chat and paste it as the first message. Add the current version of the file you're working on. That's it. You keep everything that matters and drop the noise. Habits that prevent it One chat per task. Don't debug auth and design a landing page in the same thread. Paste current code, not history. "Here's the file as it is now" beats "remember the version from earlier". Write decisions down. When you settle something ("we're using Postgres, not Mongo"), say it explicitly so it ends up in the summary. Why this matters more with agents Coding agents that edit many files burn through context even faster. A clean handoff summary between big steps keeps them on track and makes their diffs easier to review. Disclosure: I work on MadGPT. Its Coder model and VS Code agent are built for long, multi-file tasks, but the technique above works with any assistant. Drafted with AI assistance, edited by a human.

Powered by Readybot.io

**DEV Community** ## Context rot: why your AI assistant gets …