Pixel

Pixel Updates & Events

Server Updates & Events

Announcements

DEV Community

TokenBpe A editorial on how tokenizers can be sped up.

Introduction Every LLM pipeline starts with a tokenizer and almost no one thinks about it. The model gets the headlines, the tokenizer is quietly burning microseconds per token per request, forever. If you're serving millions of requests or just training on a corpus that doesn't fit in memory that "quietly" adds up. This post is a walk through TokenBpe, a BPE tokenizer that I've written from the ground up in C++20. It covers what the various components are, how each one works, what specific techniques give you a performance gain and why. All of this is based on the actual code (include/tokenizer/, src/, utils/) and the benchmark figures are from a properly audited 3 way comparison against OpenAI's tiktoken (Rust) and Hugging Face tokenizers. Headline numbers (Shakespeare corpus, 1.06 MB, GPT-2 vocabulary, 12 hardware threads, Intel i5-11260H): Operation TokenBpe tiktoken HF tokenizers Encode, 12T (zero-copy) 239.98 MB/s 45.83 MB/s 12.08 MB/s Encode, 1T 34.22 MB/s 11.55 MB/s 2.11 MB/s Decode, 1T (zero-copy) 341.01 MB/s 117.34 MB/s 24.93 MB/s ~5.2× tiktoken and ~19.9× HF on 12-thread encoding. And ~6.1× scaling from 1 to 12 threads natively. Let's open the hood. What a BPE tokenizer actually does BPE encoding has two phases: Pre-tokenisation: split the raw text into word-like pieces ("pre-tokens"). GPT-2's approach is to split on letter runs, digit runs, whitespace runs, contractions (i.e. 's, 're, 'll etc), punctuation runs and to fold the leading space into the next token (so " hello" is one pre-token rather than " " + "hello"). Merge based encoding: each pre-token is a sequence of single bytes. You repeatedly find the adjacent pair with the lowest merge rank and replace it with the merged token id, until no more merges can be applied. Decoding is trivial really: just map each token id to its bytes and concatenate. The naive implementation of this is fine. The real question is where the time goes and the answer, as ever, is everywhere, a little bit at a time. So TokenBpe attacks every layer: text ─▶ SWAR pre-tokenizer ─▶ dual-cursor split ─▶ per-thread cache ─▶ linked-list merge ─▶ token ids
with a persistent thread pool under the whole thing, a flat binary model format and a zero copy NumPy boundary on top. Component tour 1. The pre-tokenizer: SWAR instead of regex The problem is GPT-2's official tokenizer uses a regular expression to split the text. Regex engines are general purpose monsters backtracking, capture groups, Unicode classes all of which are completely unnecessary when you're just trying to determine if a run of bytes is letters or not. The technique. SWAR (SIMD Within A Register) does the 8 bytes per 64 bit word classification using pure integer arithmetic. No SSE/AVX intrinsics at all, it's all done in the 64 bit ALU. // swar.hpp (simplified)
// All 8 lanes are bytes; HIGH_BITS is OR'd in before subtracting
// min so no lane can borrow from its neighbour.
bool all_bytes_in_range(uint64_t v, uint8_t min, uint8_t max);
bool all_ascii_lower(uint64_t v); // [a-z]
bool all_ascii_upper(uint64_t v); // [A-Z]
bool all_ascii_letters(uint64_t v); // both, via v | 0x20
bool all_ascii_digits(uint64_t v); // [0-9]
bool all_bytes_equal(uint64_t v, uint8_t b);
The range check is written very carefully indeed: it rejects the high bit bytes first, then ORs in HIGH_BITS prior to subtracting min, so a lane can never borrow from its neighbour. load64 does an unaligned 64-bit load via memcpy which ends up as a single instruction. The splitter (pre_tokenizer.hpp) then scans: letter runs and digit runs 8 bytes at a time, scalar tail; space runs 8 bytes at a time with all_bytes_equal; contractions's, 't, 'm, 'd, 're, 've, 'll; punctuation runs (all other non-alphanumeric/non-space/non-apostrophe characters are grouped) And crucially next_token() returns a std::string_view into the original buffer. No pre-token is ever materialised as a string. The caller owns the text lifetime, the splitter just points into it. The speed pa...

Powered by Readybot.io

**DEV Community** ## TokenBpe A editorial on how tokenizers can …

DEV Community

SQLite on Device: A Safe Migration Path

The Situation Say you are a mobile app developer using SQLite on device for data storage. Your app has been using an older approach to manage its database, and you're looking to migrate to a newer, more efficient method without interrupting service. You've tried to update the database schema in the past, but it resulted in data corruption or app crashes, costing you a significant amount of time and user trust. The current approach is no longer scalable, and you're facing issues with data consistency and performance. Why It Happens SQLite on device is a file-based database, and updating its schema or migrating to a new approach can be challenging. The main issue is that the database is locked for writing when the app is using it, making it difficult to perform updates without interrupting service. Additionally, SQLite's transactional nature means that any errors during the migration process can leave the database in an inconsistent state. The Fix, Step by Step To migrate your SQLite database safely, follow these steps: Create a backup: Before making any changes to the database, create a backup of the current database file. This ensures that you can recover your data in case something goes wrong during the migration process. Use a temporary database: Create a temporary database with the new schema or approach. This allows you to test and validate the migration process without affecting the live database. Migrate data incrementally: Write a script to migrate the data from the old database to the new one in small chunks. This approach helps to avoid locking the database for an extended period and reduces the risk of data corruption. Validate data consistency: After each chunk of data is migrated, validate the data consistency to ensure that the migration process is working correctly. Switch to the new database: Once the migration is complete, switch the app to use the new database. This can be done by updating the database file path or by using a fallback mechanism to switch between the old and new databases. What It Costs, and When Not to Do It The safe migration path described above requires additional development time and resources to implement. However, it ensures that the migration process is done without interrupting service and minimizes the risk of data corruption or app crashes. This approach is particularly useful when working with large datasets or when the app has a high volume of user traffic. On the other hand, if the app has a small user base or a simple database schema, a more straightforward migration approach might be sufficient. At Your Level Starting out: Focus on understanding the basics of SQLite and database migration. Practice migrating a simple database schema to get a feel for the process. Working engineer: Consider using a library or framework that provides a safe migration path for SQLite, such as React Native's react-native-sqlite-storage. Implement the incremental migration approach to minimize downtime and ensure data consistency. Senior or staff: Evaluate the trade-offs between different migration approaches and consider factors such as data consistency, performance, and scalability. Develop a customized migration plan that suits your app's specific needs. Lead or director: Allocate resources and prioritize the migration effort based on the app's business requirements and user needs. Ensure that the migration plan is thoroughly tested and validated before deployment. In the Interview When discussing SQLite migration in an interview, the interviewer might ask: "How would you migrate a large SQLite database to a new schema without interrupting service?" A weak answer might focus on simply updating the database schema without considering the potential risks and consequences. A strong answer would describe the incremental migration approach, highlighting the importance of data consistency, performance, and scalability. The interviewer might follow up with questions such as: "How would you handle err...

Powered by Readybot.io

**DEV Community** ## SQLite on Device: A Safe Migration Path …

DEV Community

Git Security Release: 6 Vulnerabilities and CVE-2026-111760

Last updated: 15 November 2026. This is a recent security release; see theupdate logand check the Git announcement for changes. On 10 November 2026 the Git project released fixes for six vulnerabilities. One of them is the kind that makes developers nervous: cloning a malicious repository with git clone --recurse-submodules can lead to attacker-controlled code running on your machine. The other five are a mix of file-write, memory-corruption and denial-of-service bugs that matter most to servers and tools that handle untrusted repositories. This article walks through all six, says which ones you should worry about, shows how to check your Git version (with a script I tested), and lists what you can do until you have patched. A caution up front: the Git announcement gives no severity scores, and I could not run the exploits, so the severity talk below is based on what the maintainers wrote. The short version Fixed in: Git 2.56.1 and the maintenance releases 2.55.1, 2.54.1, 2.53.1, 2.52.1, 2.51.3 and 2.50.2. Affected: per the announcement, all versions back to v2.27.0. Versions older than 2.50 are no longer serviced upstream. The serious one: CVE-2026-111760, code execution during a recursive clone of an attacker-controlled repository. Exploited in the wild: none of the coverage I read reports it. Action: update Git, and update every tool that bundles its own copy of Git. The six vulnerabilities at a glance CVE What happens Triggered by Impact (per the announcement) CVE-2026-111760 Integer truncation in path handling lets a crafted path be written as .git git clone --recurse-submodules of an attacker's repository Remote code execution CVE-2026-113408 Unvalidated HEAD symref from a server (protocol v2) with .. segments Cloning from a malicious server, then a later operation like git commit A ref file written outside the refs directory CVE-2026-114467 More than two GPG signatures overflow a fixed array in remove_signature() Merging a tag whose message has more than two PGP signatures Stack corruption: denial of service, a risk for forges CVE-2026-114469 Binary patch size check looks only at the compressed size Applying an attacker's binary patch (for example git apply) Out-of-bounds read and crash CVE-2026-105437 Size overflow in the three-way merge buffer, with many conflicts and a large conflict-marker-size Any textual three-way merge: merge, rebase, cherry-pick, merge-tree Heap buffer overflow; on forges that read attributes from trees, a risk for anyone who can push and request a merge CVE-2026-114466 fast-import features rewrite-submodules-from/to and export-pack-edges access arbitrary files Feeding an untrusted fast-import stream Arbitrary file read (content can leak in error messages) and append CVE-2026-111760: how a clone can run code The Git maintainers describe the bug like this. Git stores the length of a path name in a 32-bit field, but computes it as a larger type. A path of about 232 bytes makes the stored length wrap around to 4. Path validation looks at the full, long name and finds nothing wrong. Checkout, however, writes only the first 4 bytes, and those 4 bytes can be .git. If the entry is a symlink, it can replace the .git file of a submodule. Normally a submodule's .git is a small file that points to the real repository directory. Pointing it at a directory the attacker controls, one that holds hooks or configuration, means Git will later run attacker-specified code. Git refuses to replace a .git directory with a symlink, but a freshly cloned submodule's .git is a file, and The Hacker News notes that this check does not block that case. Requirements, per the announcement: You clone an attacker-controlled repository with --recurse-submodules. Such a repository fails the LARGE_PATHNAME and TREE_NOT_SORTED fsck checks, so major forges would be expected to refuse a push of it. But a malicious .gitmodules in a normal-looking repository that points at one is enough. That second point is the practical risk. The ...

Powered by Readybot.io
**DEV Community** ## Git Security Release: 6 Vulnerabilities and CVE-2026-111760 …

DEV Community

Show your working: why an online calculator should print its formula

Most online calculators give you one number and nothing else. You type the area of a room and get "53 tiles". If you want to know where 53 came from, you are on your own. We built Calc around the opposite idea: the result is only half of the answer. The other half is the working. The formula with your numbers in it Under every result, the page prints the formula with your values already substituted. For tiles it looks like this: 12 m² × 1.10 ÷ 0.25 m² = 52.8, round up to the next whole tile. That one line answers the questions people actually ask. Where did the 10% go? Why 53 and not 52? Is the tile area right? Anyone can check it with a phone calculator. Assumptions as a list, not a footnote A calculation is only as good as its assumptions. Calc shows them as a list next to the result: the waste margin, the rounding rule, what the calculator does not account for. If a number depends on a rate or a standard, the constant has a source and the date it was checked. If we cannot back a number with a source, the field stays empty and asks for your own value instead of inventing a default. "I don't know this value" The hardest part of a calculator is often not the maths but the input. Next to fields where a number is hard to know, there is a card that tells you where to find it: the device spec sheet, your contract, a label, or another calculator. Nothing leaves the browser while you calculate The calculation runs in the browser. The only exception is the "calculation receipt" link: it writes the values into the address so you can send the whole scenario to a colleague or come back to it later. Because the values are in the address, the page says plainly that they end up in the server log when someone opens the link. Checked outside the code Each formula is checked against test cases by a separate calculation that does not call the site's code. If the two disagree, the calculator is wrong, not the test. That is the whole philosophy: no ads inside the result, no "AI estimates" where arithmetic will do, and a formula you can redo by hand. Calc has calculators for energy and backup power, money, small business and e-commerce, home renovation, cars, shipping and dates. They are available in Ukrainian, and most of them also in English, Polish, German and French: https://calc.uk.app/en/

Powered by Readybot.io

**DEV Community** ## Show your working: why an online calculator …

DEV Community

Turning a Spare Mini PC into an Always-On Claude Code Machine (Remote Control + tmux + cron)

Hi, I'm Shu. I'm building Memotori, an on-device transcription and summary app, for both Mac and Windows. Almost all of the code is written by AI (Claude). To make it easier to hand that work off at any time, I installed Ubuntu on a spare mini PC (ASUS VC65) and turned it into a dedicated, always-on Claude Code machine. Now I can start Claude Code sessions against the Memotori folder on that box from the Claude mobile app or from a browser (claude.ai/code), at any time. I can ask it to fix a bug while I'm out and review the diff when I get home. The key feature is Claude Code's Remote Control, which is available on the Pro and Max plans too. This post walks through: Installing Claude Code and logging in Starting Remote Control (and choosing a spawn mode) Keeping it running with tmux Starting it automatically at boot with cron Setup Machine: ASUS VC65 mini PC OS: Ubuntu Desktop Claude Code (CLI) tmux cron (@reboot) Remote Control vs. similar options Option What it does Plans Remote Control Drive Claude Code sessions running on your own machine from your phone or the web Includes Pro / Max Claude desktop app Lets claude.ai chats reach your PC's folders and screen (Windows / Mac) All plans Self-hosted runner Registers your own servers as the execution target for an organization's cloud sessions Team / Enterprise For a personal always-on box, Remote Control is the simplest choice. The CLI and the desktop app are not interchangeable: CLI (Remote Control): remote shell, file, and coding work. Runs headless. Desktop app: connects claude.ai chats to your PC, including computer use (seeing and operating the screen). If your work is mostly coding, the CLI alone is enough. You can also run both. How Memotori's folders are laid out The Mac and Windows versions of Memotori live in separate git repositories. Above them sits a shared workspace (also a git repository) that holds the specs both versions follow and the working rules for the AI (CLAUDE.md). Memotori/
├── Memotori-mac/ ← the Mac repository
├── Memotori-win/ ← the Windows repository
├── spec/ ← specs shared by both versions
├── promo/ ← promotion notes and drafts (including this post)
└── CLAUDE.md ← working rules for the AI
I run Remote Control in that shared folder. Sessions started from my phone read CLAUDE.md too, so rules like "explain the plan and get my OK before changing code" still apply. I wrote about this shared spec folder in detail in an earlier dev log. 1. Install Claude Code curl -fsSL https://claude.ai/install.sh | bash
claude --version
If claude isn't found, open a new terminal or run source ~/.bashrc. Then log in: claude
Follow the browser login, then type /exit. 2. Start Remote Control Go to your project folder and start it: cd ~/develop/projects/myapp
claude remote-control
The first time, it asks: Spawn mode for this project:
[1] same-dir — sessions share the current directory (default)
[2] worktree — each session gets an isolated git worktree
This setting decides which directory each new session works in when you start one from your phone or the web. Mode Behavior Best for same-dir All sessions share the current directory One task at a time, or folders without git worktree Each session gets its own git worktree (an isolated working copy) Running several sessions in parallel Pass the mode as a flag so you aren't prompted again: claude remote-control --spawn=worktree
Notes on worktree mode The folder must be a git repository with at least one commit: git init
git add . && git commit -m "init"
Each session works on its own branch, so you (or Claude) merge the results. Untracked files such as .env are not copied into worktrees. Clean up occasionally: check with git worktree list, then run git worktree prune. 3. Keep it running with tmux Run it inside tmux so it survives SSH disconnects: sudo apt install -y tmux
tmux new -s claude
claude remote-control --spawn=worktree
Detach with Ctrl+B then D. Reattach with tmux at...

Powered by Readybot.io

**DEV Community** ## Turning a Spare Mini PC into an …

DEV Community

JavaScript noindex Removal: Fix the Initial HTML Before Trusting the DOM

If a public page's initial HTML contains a noindex robots tag, do not rely on JavaScript to remove it later. Fix the initial response for the pages intended to be indexed, then verify the rendered document and the route states separately. A clean browser DOM is useful evidence, but it does not erase an earlier directive in a different processing path. For a SaaS team, this can hide a clear buyer answer behind a template mistake. The product page may describe a real capability, load normally and pass a visual review. The writer keeps improving the answer while the original response still tells a search engine to exclude it. Trace the directive before expanding the copy. Establish the intended policy for the exact URL Start by naming the public page and deciding whether it is supposed to be eligible for indexing. Record the full URL, including any query string relevant to the problem. Do not begin by deleting every noindex tag across the application. A public product explanation and a private account screen have different purposes, even when they share a frontend shell. Write down the reason for the intended policy. A product guide may answer a buyer question that the company wants people to find. A temporary internal preview may intentionally stay out of search. That distinction belongs in the diagnosis, so a developer does not “repair” a deliberate publishing choice while trying to help marketing. Keep access protection separate from this editorial policy. Removing an indexing directive is not a reason to publish private content or weaken authentication. Work on a public, approved page and preserve the existing protection around other routes. If the intended audience is unclear, resolve that specific question with the page owner before changing the response. Inspect the initial HTML before the rendered head Google's JavaScript SEO documentation warns that encountering noindex may cause Google to skip rendering and JavaScript execution. Removing or changing that tag with JavaScript may therefore fail to have the intended effect. Google advises against putting noindex in the original code when the page should be indexed. Use that documented behavior to choose the first diagnostic step. Capture the response for the exact public URL using your normal development tools. Search the returned HTML for robots directives and retain the relevant portion of the head. Record the response conditions and release version alongside the finding so another developer can reproduce it. Then inspect the rendered head in a fresh browser load. Compare what arrived with what the application eventually produced. If the initial response says noindex and the later document does not, that difference is the issue to investigate. Avoid calling the later DOM the “real page” in a way that makes the earlier response disappear from the evidence. Trace which layer supplied the directive A fictional product, Fieldglass Notes, uses one application shell for public guides and account pages. Its public guide about approval history receives a default noindex tag. After the page loads, a component removes the tag for public content. This is a hypothetical failure pattern, not an observed behavior of a real service. The fix begins with ownership. Ask which part of the publishing path creates the initial head: a template, a route-specific server response, a static export or another documented layer in that application. Follow the actual output back to its source. Do not assume the page component that removes the tag also owns the response that added it. Propose a narrow change: public guide URLs receive their intended initial indexing policy, while account and preview routes keep theirs. Review a representative URL from each affected class. The important regression question is not merely whether one guide lost noindex. It is whether the implementation now applies the right policy to each type of page it serves. Verify direct loads and client-side navigation Test a d...

Powered by Readybot.io

**DEV Community** ## JavaScript noindex Removal: Fix the Initial HTML …

DEV Community

Building a Bench of Senior Developers Without Sitting on Idle Cost

Every software services firm lives with the same tension. When a new client says yes, they want a strong team next week, not in two months. But every senior developer sitting on the bench waiting for that yes is pure cost. Carry too much bench and margin disappears. Carry too little and you either lose the deal or staff it with whoever happens to be free. Earlier in my career, as a partner, I helped grow a software consulting company from about $6M to $60M in under three years, and later I founded and ran a fully remote consultancy. At that pace of growth, bench strategy is not a side topic. It decides whether you can say yes to good work, and whether saying yes leaves you any profit. Here is how I think about building a bench of senior developers without sitting on idle cost. Why the Bench Is a Strategy Problem, Not a Staffing Problem Most firms treat the bench as an accident. People roll off a project, nobody has lined up their next one, and they wait. That kind of bench is expensive and demoralizing, because nobody chose it. A healthy bench is deliberate. You decide how much ready capacity the business needs to win and start work quickly, you decide which skills belong on it, and you decide what bench time is for. Once you make those choices on purpose, the bench stops being a leak and becomes a sales and delivery asset. Size the Bench From Your Pipeline, Not From Hope The right bench size comes from the sales pipeline, not from a gut feeling. Look at deals by stage and likely start date. A signed deal starting in two weeks needs named people now. A deal still in discovery needs a rough plan, not idle engineers. Plan for the roles that are hardest to find. Mid-level developers are usually easier to source quickly. Senior engineers and tech leads who can face a client on day one are not. Those are the people worth keeping ready. Review it every week. Pipeline and roll-off dates change constantly. A short weekly meeting between sales and delivery, looking at who rolls off when and which deals are close, prevents most bench surprises. Make Bench Time Productive Bench time does not have to be wasted time. The firms that handle it well give senior people real work between client projects. Internal tools and accelerators. Starter templates, deployment scripts, test harnesses and reference architectures make every future engagement start faster. Senior people on the bench are the right people to build them. Pre-sales support. A senior engineer who joins discovery calls, writes technical approaches and estimates scope makes proposals sharper and wins more of them. It also means the person who scoped the work can lead it. Shadowing and overlap. Placing a bench engineer on an active project for a few weeks, at reduced or no cost to the client, builds context before a planned rotation and makes future handoffs far smoother. Skill building with a target. Learning should point at demand you actually see in the pipeline, not at whatever is trending. Use a Flexible Outer Ring You do not need to carry every possible skill as full-time bench. A small core of senior people, surrounded by a trusted outer ring, covers far more ground. That outer ring can include vetted contractors you have worked with before, partner firms with complementary skills, and alumni who left on good terms and would come back for the right project. The key word is vetted. The outer ring only works if you already know the quality of the work, so you are not running a fresh hiring process every time a deal closes. Running a fully remote consultancy made this much easier. When you hire across regions and time zones, the pool of strong senior people is larger, and you can match people to projects instead of to an office. Watch the Right Numbers A few simple measures tell you whether the bench is healthy. Utilization of senior people over a quarter, not a week. Short dips are normal. A senior engineer on the bench for months is a signal that either sales or staffing h...

Powered by Readybot.io

**DEV Community** ## Building a Bench of Senior Developers Without …

DEV Community

Building a Consistent AI Art Pipeline for a Tarot Content Site

The problem We run a small tarot reading site and needed a steady stream of original illustration for articles and social posts. Stock fantasy art is either overused, wrong in mood, or licensed awkwardly. Hiring an illustrator for every post didn't scale. The obvious answer was AI image generation — but anyone who has tried it for a brand knows the real problem isn't generating a pretty picture, it's generating the same pretty picture, on demand, with a consistent palette and iconography. This post walks through the pipeline we settled on and what we learned about controlling style. Defining a reproducible style Our anchor visual is what we call the "Moon Oracle" composition: a robed figure with long violet hair seated among clouds, holding a glowing astral sphere, framed by a row of moon phases across the top, lit candles in brass holders, and amethyst / quartz crystals at the base. Deep purples and gold carry the whole palette. To make that reproducible we broke it into a controlled prompt schema rather than freeform prose: Subject block: figure, pose, key prop (the star-and-orbit sphere), expression direction Iconography block: moon phase arc, constellation embroidery on the robe, crystal clusters, candlesticks Style block: digital painting, luminous cell-shaded rendering, nebula backdrop, symmetric composition Color block: dominant violet/purple, gold accent stars, warm candle glow as the only warm light source One useful trick: treat the color block as non-negotiable and the subject block as variable. That's what lets us generate variations — a card-specific figure, a different season backdrop — while everything still reads as the same brand on a feed thumbnail. Generation and refinement loop The workflow is roughly: Draft with an open diffusion model, CFG around 7, heavy negative prompts (extra fingers, cluttered borders, watermark artifacts). Generate 8–16 candidates per concept at low resolution. Hand-select candidates on composition first, detail second — silhouettes and symmetry read at thumbnail size, small details don't. Upscale the survivors, then do targeted inpainting on hands, faces, and the sphere's orbit lines, which are the three things diffusion models reliably get wrong. The moon phase arc is a good example of why inpainting matters. Models can paint a moon, but a correctly ordered sequence — waxing crescents through full moon to waning — almost never comes out right from the base prompt. We composite or inpaint that band explicitly. Results and tradeoffs What worked: throughput went from days per illustration to hours, and the consistent violet-and-gold look gives the site a recognizable visual identity that plain stock art never did. What we gave up: Hands and jewelry still need manual fixes on most finals. Budget for an inpainting pass every time. Symbolic accuracy is on you. If a moon phase arc is wrong, no model will care. Astrological and tarot imagery demands a human review step for correctness, not just aesthetics. Over-uniformity risk. Lean too hard on the style block and every image looks like a recolor of the last. We keep the subject block loose enough that compositions stay varied. The biggest lesson: treat AI art like code — define a spec (the prompt schema), automate the boring parts (batch generation, upscaling), and keep a human review gate for anything that claims to be symbolically meaningful. If you want to see the output of this pipeline in the wild, the illustrations live on our site: https://oracleblooms.top AI-generated 'Moon Oracle' illustration: a violet-haired robed figure seated among clouds holding a glowing star-orbit sphere, with a seven-phase moon arc overhead, constellation embroidery on the gow

Powered by Readybot.io

**DEV Community** ## Building a Consistent AI Art Pipeline for …

DEV Community

How to Build an Offline, On-Device Voice-to-Voice AI Agent in React Native

Short answer: To build an on-device Voice-to-Voice AI Agent in React Native, chain five stages that all run on the phone: a wake word detector, optional speaker verification, speech-to-text (STT), a small local LLM that calls your app's tools, and on-device text-to-speech (TTS). Stream the LLM's reply into TTS sentence by sentence, and hand the microphone carefully between stages. This tutorial does exactly that with the open-source DaVoice React Native example app and three npm packages from the DaVoice Voice AI Agent SDK: react-native-wakeword, react-native-davoice and react-native-davoice-llm. The result is an agent that listens for "Hey Coach", understands "open the rear right window", runs a real function in your app, and answers out loud: "I opened the rear right window." No cloud LLM, no per-token bill, and no audio leaving the device during the voice loop. What "token-free" means here. A local LLM still processes tokens. "Token-free" means you pay no cloud LLM inference token fees, because inference runs on the user's phone. DaVoice SDKs are licensed separately; evaluation and non-commercial proofs of concept are free, and production use needs a commercial license. Used in production The same on-device voice stack already runs in shipped products: Verbali (MaTalk AI, an AAC app for non-verbal children) moved its wake word, speech-to-text and text-to-speech fully on-device with DaVoice, so no audio leaves the tablet and voice keeps working without internet. In Verbali's own write-up, DaVoice reached 97.65% wake word accuracy with zero false positives observed on their test setup, versus about 75% for the other engines they evaluated. In their words: "We have no affiliation with DaVoice beyond being a happy customer." Volkswagen chose DaVoice for OTTO, its generative AI car assistant launched in Brazil (customer story · video). LunaFit built its entire voice-to-voice AI agent on DaVoice, including speaker-aware speech-to-text that hears its user in a noisy gym (video). The interruption pattern in section 8 comes from LunaFit's workout mode. Table of contents What you will build Architecture: wake word → STT → local LLM → TTS What is really offline (and what is not) Prerequisites Run the DaVoice example app Implementation, stage by stage Add the agent to your existing React Native app Advanced: speaker verification, voice cloning, interruptions Testing and troubleshooting FAQ Resources 1. What you will build A hands-free assistant inside a React Native app (iOS and Android) that: listens continuously for a custom wake word ("Hey Coach" in the example); optionally checks that the speaker is the enrolled owner; transcribes the request in real time; lets a 0.6B-parameter on-device model decide whether to call one of your app's tools, ask a clarifying question, decline, or hand the request to an (optional) remote model; speaks the result with an on-device neural voice, which can be a cloned voice. The example ships two demos you can try immediately: Demo Model (downloaded on first use) Tools Car demo DaVoice Automotive Agent 0.6B (~380 MB GGUF) 22 simulated car tools: windows, doors, locks, climate, navigation, radio Calories demo DaVoice Personal Agent 0.6B (~380 MB GGUF) calorie tracker, personal memory, web search Honest status from the repo: the automotive model is labeled a test model, still in training. On DaVoice's frozen automotive test set it gets about 82% of Brazilian Portuguese commands exactly right (tool + arguments) and picks the right tool about 90% of the time. Every car action is simulated and checked by app-side guards. Treat it as a preview of the voice pipeline, not final accuracy. 2. Architecture: how a Voice-to-Voice AI Agent works on-device ┌────────────────────────── on the phone ──────────────────────────┐
microphone ──► │ Wake word ──► Speaker ──► Speech-to- ──► Local LLM │
│ "Hey Coach" verification text (STT) Agent │
...

Powered by Readybot.io

**DEV Community** ## How to Build an Offline, On-Device Voice-to-Voice …

DEV Community

GitHub Actions unexpected symbol in a ${{ }} expression

GitHub Actions unexpected symbol in a ${{ }} expression means the expression parser reached a character it has no rule for and stopped. The YAML is fine, the workflow never starts, and the message hands you the offending token, its position and the expression it came from, which is usually enough to fix it without running anything. Four fields in one line. The file position points at the YAML key, the position inside the expression points at the character that stopped the parser. What this error means The workflow does not run at all. There is no job, no log and no annotation on a step, because the file was rejected before any of that existed; GitHub shows it as an invalid workflow file against the line in the editor and in the commit status. The message has four parts, and each one is doing work. It names the file and the line and column of the YAML key that holds the expression. It names the kind of problem. It gives you the raw token it choked on, in quotes. Then it gives you a position inside the expression and the expression text itself, so you can count across to the character it means. The position is an index into the expression, not into the file, which is the part that sends people to the wrong place first. ```Invalid workflow file, quoted from SciKit-Surgery/sustainable-pkg-stats#24 The workflow is not valid. .github/workflows/tests.yml (Line: 33, Col: 27): Unexpected symbol: '-'. Located at position 7 within expression: '{{ ' -

Common causes

A string literal in double quotes

The single most common one, because every other language in the repository accepts them. The parser reads the opening double quote as a symbol with no rule attached and reports it immediately, usually with the quote and the first word of the string as the raw token.

An operator the expression language does not have

Arithmetic, a single & or |, a bare =, or a ternary. The operator table has twelve entries and none of those are in it. In our experience this arrives when logic that belongs in a run: step is being squeezed into a condition.

A stray or mismatched brace

A ${{ opened twice, a }} that closes the wrong one, or a quoted YAML scalar that swallowed part of the delimiter. The parser then receives a fragment, and the token it reports is whatever punctuation was left dangling, which is why the position often points somewhere that looks fine.

Literal text glued to an expression

Concatenating by writing text next to ${{ ... }} inside the same expression rather than outside it. The parser reads the text as a symbol. The format() function exists for this, and it keeps the quoting in one place instead of three.

How to fix it

Swap the double quotes for single quotes

  1. Find the token the message printed in quotes and locate it in the expression text on the same line.
  2. Replace the surrounding double quotes with single quotes, and double a literal single quote to escape it.
  3. Leave YAML quoting alone: this is about quotes inside the expression, not around the whole value.

.github/workflows/ci.yml (illustrative) if: ${{ github.event.head_commit.message == 'it''s fine' }} Rewrite the logic with operators that exist Use && and ||, and reach for contains(), startsWith() or format() rather than inventing syntax. Anything that needs arithmetic or a ternary belongs in a step, where the shell can do it and the result can come back as a step output..github/workflows/ci.yml (illustrative) if: ${{ startsWith(github.ref, 'refs/tags/') && github.event_name != 'pull_request' }}

Count the delimiters before you count the characters

When the expression printed at the end of the message does not look like the one you wrote, the problem is the delimiters rather than the contents. Check that each ${{ has one }}, and that a value wrapped in YAML quotes has not absorbed part of either.

Lint the expressions, not just the YAML

A YAML validator will pass a file that the expression par...

Powered by Readybot.io

**DEV Community** ## GitHub Actions unexpected symbol in a ${{ …

DEV Community

One Hand-Typed Number Made My Drug Valuation 4.5x Too High

My drug valuation desk said a Phase 2 cancer drug was worth $1.29 billion. After two small fixes, the same drug with the same sales forecast was worth $283.5 million. Neither bug crashed anything. The screen looked great the whole time. That is the kind of bug this post is about. The setup The desk is called Somota. My company Codebat finished the first version in March 2025, under the name PharmFlow. It values a drug with risk-adjusted NPV (rNPV): forecast the cash flows, then weight them by the chance the drug actually reaches the market. This week my AI coding assistant was tracing where every input on the screen came from. Most inputs had a source. One did not. Bug 1: a success rate with no source The probability of success for the cancer asset was 30%. I had typed it in by hand, a long time ago, and nothing on the screen said so. The best public benchmark I know of is the BIO, Informa Pharma Intelligence and QLS report, Clinical Development Success Rates 2011-2020 (February 2021). It gives the odds of passing each phase transition, by therapy area. For oncology: Transition Success rate Phase 1 to Phase 2 48.8% Phase 2 to Phase 3 24.6% Phase 3 to filing 47.7% Filing to approval 92.0% A drug in Phase 2 still has three of those doors in front of it. The chance it gets through all of them is the product: BENCH = {
"oncology": {"p12": 0.488, "p23": 0.246, "p3n": 0.477, "pna": 0.920},
}
STAGE_STEPS = {
"Phase 1": ("p12", "p23", "p3n", "pna"),
"Phase 2": ("p23", "p3n", "pna"),
"Phase 3": ("p3n", "pna"),
}

def bench_pos(asset):
"""Likelihood of approval from the asset's current phase."""
b, v = BENCH[asset["area"]], 1.0
for k in STAGE_STEPS[asset["stage"]]:
v *= b[k]
return round(v, 4)

bench_pos({"area": "oncology", "stage": "Phase 2"}) # 0.108
So 10.8%, about one in nine. The model had 30%. Bug 2: costs multiplied by the same probability The second bug was in how development costs were risk-adjusted. The old code did roughly this: risked_dev_cost = development_cost * launch_probability
That treats every dollar of trial spending as if it only happens when the drug succeeds. It is like a college saying you will probably drop out, so it will only charge you 30% of the tuition. Real trial bills do not work that way. You pay for the trial you are running now in full. You only pay for the next trial if this one works. So each year of spending gets its own weight: the chance of still being in development that year. def cost_weights(asset):
"""Development cost is spent over 3 years. Year 1 is the current phase,
paid for sure. Each later year is paid only if the trials before it passed."""
b, s = BENCH[asset["area"]], asset["stage"]
if s == "Phase 1":
w = [1.0, b["p12"], b["p12"] * b["p23"]]
elif s == "Phase 2":
w = [1.0, b["p23"], b["p23"] * b["p3n"]]
else: # Phase 3 runs two of the three years, then filing
w = [1.0, 1.0, b["p3n"]]
return [round(x, 4) for x in w]

cost_weights({"area": "oncology", "stage": "Phase 2"}) # [1.0, 0.246, 0.1173]
The result Same asset: $1.5B peak sales, 12.5% discount rate, $600M development cost to go, three years to launch. Old Fixed Probability of success 30%, hand-typed 10.8%, sourced Development cost weights x 0.30 every year 1.0, 0.246, 0.117 Risk-adjusted NPV $1,292.2M $283.5M Then I ran a tornado chart: push each input up and down and see how far the value moves. Success rate, plus or minus 10 points: $755.8M swing Discount rate: $216.1M swing Peak sales: $206.6M swing The one input nobody had sourced was the one that moved the price the most. A check you can copy This works on any model, not only drug valuations. Put a source label next to every input on the screen: public data, computed from public data, or typed by hand. Run a sensitivity check and sort the inputs by how far they move the output. Look at the top of that list first. If the biggest driver is typed by hand, go find a source before...

Powered by Readybot.io

**DEV Community** ## One Hand-Typed Number Made My Drug Valuation …

DEV Community

Put yourself in a viral clip with one photo — no prompt

I shipped Genjutsu AI — a small web tool for a narrow job: take a video people already share, swap the people for photos you pick, and keep the original take. No prompt. No storyboard. You upload the clip, the app splits it into scenes and lists who’s in frame. You add one still photo per person you want to change. Everyone else, the background, and the props stay as filmed. What stays the same Shot order, timing, and camera Cuts and pacing Original audio What changes Only the people you assign a photo to. One photo = one identity across every shot they appear in. That can be you, a friend, a pet, a product, or a character. How it works Upload mp4, mov, or webm (up to 80MB), or pick a template (Hotel Lobby, Tiny Desk AI, Night Dance, Bulin 47, and others). Scenes and faces are detected automatically. Attach a photo for each face you want to replace. Generate. Download is 720p with the source audio. Under the hood it’s a Next.js app with a Python cast pipeline for scene/face work, Prisma + Postgres for accounts and credits, object storage for uploads, and a video model API for the swap. Happy to talk stack details in the comments if anyone’s curious. Limits worth knowing Rule Detail Scene length A single scene cannot exceed 15 seconds (shorter clips work best). Resolution Output is 720p. Credits 10 credits per 15 seconds; failed runs refund credits. Sign-in Google — generations stay on your account. Credits don’t expire. First 15-second video on Starter is $6.90, then $9.99 (10 credits). Plus and Creator packs are on the pricing page. Not the same as “Higgsfield Genjutsu” Genjutsu AI is a separate product: you bring the video, and you attach one photo per person you want in the frame. Same filmed motion, different faces. Try it 👉 ai-genjutsu.com A clip under 15 seconds is enough for a first run. I’d love feedback on scene splits, face consistency, and whether the credit pricing feels fair — especially from folks who ship short-form or meme clips. Disclosure: I built this. It’s a paid credit product, not open source.

Powered by Readybot.io

**DEV Community** ## Put yourself in a viral clip with …

DEV Community

Why is my AWS bill so high when traffic is flat?

An AWS bill that climbs while traffic stays flat usually has one of three causes: data nobody deletes keeps piling up, a discount has ended, or a new charge started on a set date. To see why your AWS bill is so high, compare the month before the climb with the latest one in Cost Explorer. Compare two months in Cost Explorer Open the free Compare view under Report parameters, pick two of the last 13 months and group by service. According to the cost comparison documentation, Compare shows the three biggest changes and names the reason for each: usage, discounts, or other charges and credits. Usage rising by a similar amount every month points to data that only grows. If traffic is flat and AWS puts a jump down to discounts or credits, a Savings Plan or reservation has usually expired, or your credits have run out. Then filter to the growing service in the normal Cost Explorer view and group it by Usage type. The chart for this part is in the original post. A slow climb usually triggers no alert. According to the Cost Anomaly Detection FAQ, the default setup alerts only when an anomaly exceeds both 40% of expected spend and $100. A budget with a lower threshold warns sooner; see the post on AWS budget alerts. S3 versions, ECR images and RDS storage With versioning on, S3 keeps every version of a file as a separate, full object at the normal rate. Deleting a file frees nothing, because S3 only adds a delete marker. Incomplete multipart uploads grow the same way and are billed until someone completes or aborts them. S3 Storage Lens shows both in two free metrics, Noncurrent version bytes and Incomplete multipart upload bytes. ECR, the container image registry, also fills up when every deploy pushes a new image. A lifecycle policy removes old images by count or age. Check it in the lifecycle policy preview first, as AWS advises, and keep enough recent images to roll back. On RDS the disk grows. With storage autoscaling on, AWS enlarges it by itself when space runs low but never shrinks it, so you keep paying for the added gigabytes after the data is deleted. Manual RDS snapshots ignore the retention period and stay until you delete them. CloudWatch logs never expire by default. I cover them, and EBS snapshots left behind by old scripts, in what I check in an AWS cost audit. A lifecycle rule for S3 The rule below covers the whole bucket: it deletes versions that have been noncurrent for 30 days and aborts uploads older than 7 days. The put command replaces every existing rule on the bucket, so read the current rules first and copy any you want to keep into the file. If one of them keeps old versions longer than 30 days, leave this rule out: where rules overlap, S3 honours the shorter expiration. The commands are for AWS CLI v2. aws s3api \
get-bucket-lifecycle-configuration \
- -bucket my-bucket
Save the rule as lifecycle.json: {
"Rules": [
{
"ID": "cleanup",
"Status": "Enabled",
"Filter": { "Prefix": "" },
"NoncurrentVersionExpiration": {
"NoncurrentDays": 30
},
"AbortIncompleteMultipartUpload": {
"DaysAfterInitiation": 7
}
}
]
}
aws s3api \
put-bucket-lifecycle-configuration \
- -bucket my-bucket \
- -lifecycle-configuration \
file://lifecycle.json
Deleted versions cannot be recovered, so if you reach for old files months later, raise NoncurrentDays. When a Savings Plan or reservation ends Neither a Savings Plan nor a reservation renews itself. Once an RDS reservation ends, the database is billed at the on-demand rate. Before a Savings Plan ends, you can queue a new plan or click Renew Savings Plan. Turn on the expiry email under Manage alert subscriptions on the Savings Plans page. Year three of RDS Extended Support RDS adds an Extended Support charge for MySQL and PostgreSQL versions whose standard support has ended, and doubles it in year three. According to RDS pricing on 11 November 2026, a 2-vCPU database on MySQL 5.7 in Frankfurt (eu-centr...

Powered by Readybot.io

**DEV Community** ## Why is my AWS bill so high …

DEV Community

How to Catch Missing .env Variables and .env.example Drift Before Production Deploy

Originally published at umutgungorr.com. How to stop silent .env vs .env.example configuration drift and undocumented os.getenv calls in CI before a missing environment variable breaks production. Why code that passes locally crashes on deploy Adding a new key to your local .env file while building a feature takes seconds. Forgetting to mirror that key in .env.example and your deployment environment usually stays invisible until production traffic hits that branch and fails with a KeyError or empty string. Missing keys are only half the problem: stale variables accumulate in templates over time, new teammates cannot tell which keys are actually required, and local onboarding slows down. Step 1: Enforce the .env ↔ .env.example contract in CI Treating configuration drift as a build failure rather than a passive warning is the cleanest fix. The zero-dependency envdoctor-cli package compares .env against .env.example and exits non-zero whenever keys drift. pip install envdoctor-cli

.env ile .env.example arasındaki eksik veya fazla anahtarları kontrol et

envdoctor check --strict

Eksik anahtarları gerçek değerleri sızdırmadan maskeli yer tutucuyla ekle

envdoctor sync
Step 2: Surface undocumented env vars in source code with AST Comparing two env files is not enough on its own: a developer may add os.getenv("NEW_WEBHOOK_SECRET") in Python code without documenting it in either .env or .env.example. Regex greps misfire on comments and string literals, whereas Python AST analysis extracts actual environment lookups directly from the syntax tree. # Kaynak kodda os.getenv / os.environ çağrılarını tara ve CI için JSON üret
envdoctor audit --format json
Step 3: Add a 5-line gate to GitHub Actions Running both template validation and AST auditing on every pull request catches undocumented environment keys before the branch is merged. The check validates key names only and never transmits secret values. name: Env Contract Check
on: [pull_request]
jobs:
envdoctor:
runs-on: ubuntu-latest
steps:
- uses: actions/checkout@v4
- uses: actions/setup-python@v5
with:
python-version: '3.12'
- run: pip install envdoctor-cli && envdoctor check --strict && envdoctor audit
References EnvDoctor project page and architecture notes PyPI: envdoctor-cli package GitHub: umutgungorr/envdoctor Designing CLI Tools That Earn Trust

Powered by Readybot.io

**DEV Community** ## How to Catch Missing .env Variables and …

** Latest from PC Gamer **

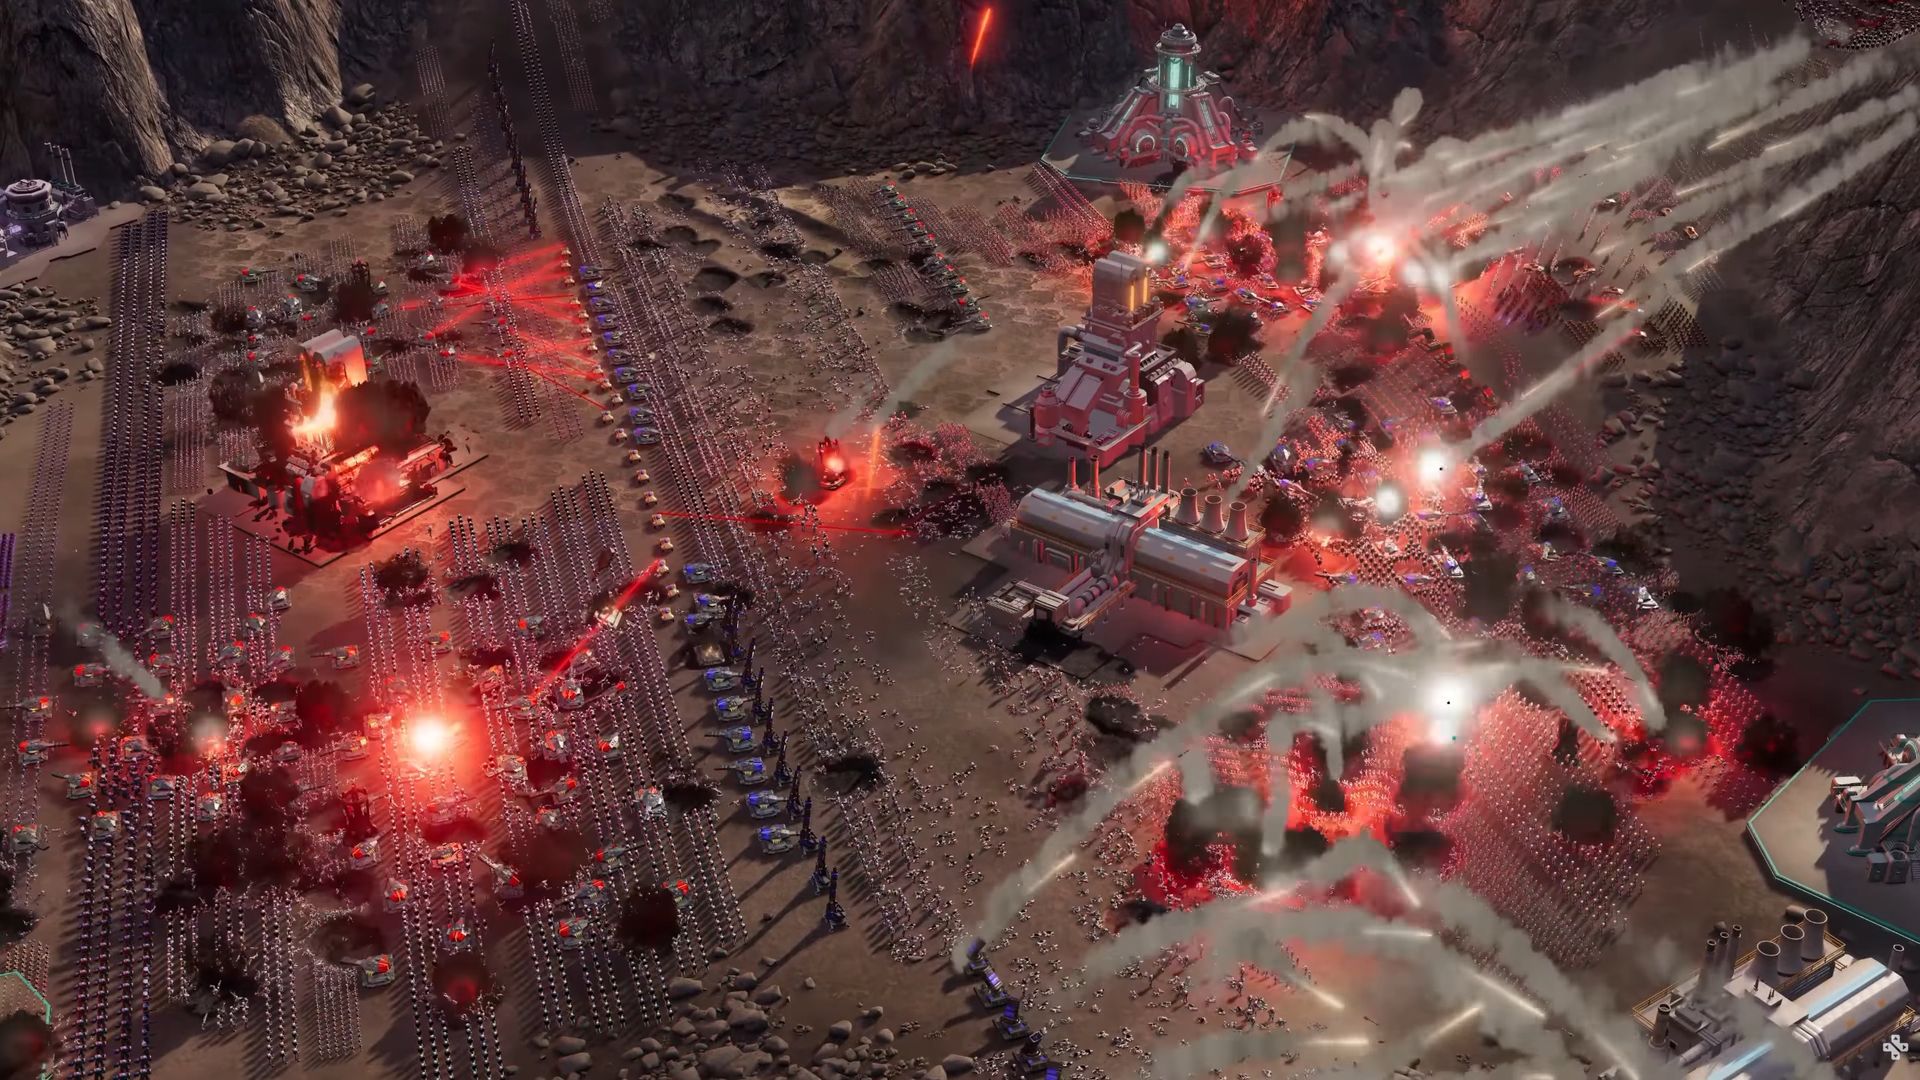
This RTS inspired by Star Wars: Empire at War promises colossal space encounters and planetary battles with 'hundreds of thousands of units'

Horu is expected to launch at the end of next year.

Powered by Readybot.io

** Latest from PC Gamer ** ## This RTS inspired …

IGN India Pc

Fortnite - Official Treasure Hunters Week 3 Gameplay Trailer

Check out the Fortnite Treasure Hunters Week 3 gameplay trailer as the duo you didn't know you needed, Hatsune Miku and Kasane Teto, land on the Island! See the two iconic virtual singers in action in Fortnite Treasure Hunters, available now.

Powered by Readybot.io

**IGN India Pc** ## Fortnite - Official Treasure Hunters Week …

DEV Community

Thread Milling vs Tapping vs Rolling: What Actually Changes in the Quote

Six M3 taps in one afternoon. That's what started this. A batch of 17-4 PH stainless parts, M3 × 0.5, 8 mm deep, blind. The operator was running them on a VMC with a tapping cycle, and by the third hour he'd broken six taps and had two stuck in the holes — which meant two scrapped parts, because a broken tap in 17-4 is not coming out. Nothing was wrong with the taps. The problem was the method. There are four ways to put a thread in a part, and they are not interchangeable. Each one changes the quote, the risk, and sometimes the design. Tapping A cutting tap removes material. It's fast, the tooling is cheap, and on aluminum and mild steel it's the default answer. Where it goes wrong: chip evacuation. In a blind hole, chips have nowhere to go except back up the flutes, and the deeper you go the worse it gets. Form-factor taps (spiral flute, spiral point) help, but below about M4 the tool cross-section is so small that a chip jam equals a snapped tap. In 17-4 PH, work-hardening makes it worse. The material gets harder where the tap rubs, so a slightly dull tap doesn't cut — it burnishes, then breaks. Form tapping (thread forming) No chips at all. The tool cold-forms the material instead of cutting it. The resulting thread has continuous grain flow and is measurably stronger in fatigue than a cut thread. Two catches. First, the tap hole is different — form tapping needs a larger pilot hole than cutting (roughly the pitch diameter minus half the pitch, but check the tap maker's chart). Second, it takes more torque, which means more spindle power and a rigid setup. On thin-walled parts it can distort the wall. Works well in aluminum, brass, and low-carbon steel. Poor in cast iron and anything brittle. Thread milling A single-point or multi-flute thread mill follows a helical path. The tool is small relative to the hole, so there is no chip packing problem, and if the tool breaks it breaks into small pieces that flush out instead of wedging in the hole. This is the answer for hard materials, large threads, and any hole where a broken tap would scrap the part. It also lets you cut a thread with an interrupted profile, or reach a thread right up to a shoulder where a tap couldn't. The cost: cycle time. A single-point thread mill on an M3 hole takes maybe 10–20 seconds; a tap takes two. And the machine needs helical interpolation, which every modern VMC has but older ones may not. Where thread milling wins economically: M16 and up, where the tap is expensive and the torque is high. At M20 in steel, a thread mill often costs less per part than the tap does per hole, because the mill lasts hundreds of holes and the tap doesn't. Thread rolling (external) Cold-forming an external thread between two or three dies. This is a different animal — it produces the strongest thread available, with uninterrupted grain flow and a compressive residual stress at the root. For studs, shafts, and anything fatigue-critical, it's the right process. But it needs a dedicated machine or a rolling attachment, and it only does external threads. Job shops usually send this out. What it does to the quote Rough hierarchy for a small thread in a small hole: Tapping, aluminum, through hole: cheapest, no discussion needed. Form tapping, aluminum: same order of magnitude, better thread. Tapping, stainless or hardened: risky. Price it with a breakage allowance, or don't price it at all. Thread milling, any material: 2–5× the cycle time of tapping, near-zero scrap risk. Thread rolling: a separate operation, quoted separately. The trap is quoting tapping on a material where breakage is likely. If the shop doesn't add a risk allowance, they either eat the scrap or the part arrives late. Both are worse than a slightly higher price. What to put on the drawing Thread callout alone isn't enough. Specify: Class: 6H for internal, 6g for external (or 2B/2A in inch). Depth: thread depth and drill depth separately. A blind hole needs the drill to go deeper than the thread, an...

Powered by Readybot.io

**DEV Community** ## Thread Milling vs Tapping vs Rolling: What …

DEV Community

llama.cpp Just Hit 1.0, and Local AI Finally Has a Promise to Stand On

Have you ever built something on top of a tool that changed underneath you? You write code against a library, everything works, and then one update quietly moves a function or renames a setting. Nothing explodes. Your code just stops compiling on a Monday morning, and you spend the day figuring out what moved. If you run AI models on your own computer, you have probably lived this. On November 13, the project at the bottom of that whole stack finally made a promise that it will stop happening without warning. llama.cpp, the open-source engine that runs large language models on ordinary hardware, released version 1.0.0. The engine you already use, even if you never installed it First, a quick explainer, because llama.cpp is one of those things that is everywhere and invisible at the same time. It is not a chatbot and not a model. It is the engine: a small, fast program written in C and C++ that loads a model file and runs it on your laptop, your desktop, or a server. You have probably used it without knowing. Tools like Ollama and LM Studio, the friendly apps people use to chat with models on their own machines, build on llama.cpp underneath. When you run a model locally instead of sending your prompts to someone else's cloud, there is a good chance llama.cpp is doing the actual work. The project has been around for about three and a half years, and for all that time it versioned itself with plain build numbers: b1234, b12359, and so on. Each release was just the next number in line. There was no way to look at a version number and know whether upgrading would break your code. Photo by Kevin Ache on Unsplash What 1.0 actually promises Version 1.0 changes that, and the change is a promise, not a feature. From now on, llama.cpp and its underlying tensor library, ggml, follow semantic versioning. The rule is simple: a breaking change to the public C API only ever arrives with a major version bump. A new feature or new model support gets a minor bump. A bug fix gets a patch bump. Think of it like a building finally getting its foundation inspected and certified. The house does not look any different from the street. But now there is a document saying which walls are load-bearing, and nobody is allowed to move one without telling you first. That is what 1.0 is: a signed contract between the maintainers and every developer building on top of them. And the timing makes sense. The announcement says many downstream applications already depend on the project, and it now supports more than 150 model architecture variants. When that many apps stand on your work, a stable public API stops being a nice idea and becomes the job. The cleanup that came with it A 1.0 release is also a good moment to throw things out, and this one did: the deprecated public API is gone, including 35 deprecated functions. There are smaller improvements too, like FP8 key-value caches that use less memory and security hardening for llama-server. But none of that is the headline. The headline is the version number itself. The honest fine print Here is the part worth reading twice. A stable version number does not mean nothing will ever break. The promise covers the public C API, the headers in the include directory. It does not cover every command-line flag or every model file forever. And 1.0 itself is a breaking change if your code still calls one of those 35 removed functions: it will fail at compile time, which is exactly the kind of break the new rules are designed to announce in advance next time. That is the deal, and it is a fair one. You get a clear signal about what changed and how much it matters. In return, the maintainers get to keep moving fast without quietly pulling the floor out from under you. So if you build anything that runs models locally, or you are thinking about it, this quiet release matters more than most loud ones. The engine underneath local AI just grew up a little. It put its promise in writing. What would you build if you could tru...

Powered by Readybot.io

**DEV Community** ## llama.cpp Just Hit 1.0, and Local AI …

DEV Community

How Many Shops Should You Quote? The Math Behind 2 vs 5

The question comes up in almost every sourcing thread: how many shops should I quote before I pick one? Most answers are folklore — "always three," "at least five," "get seven and average them." None of those survive contact with what actually happens when you send an RFQ. Here's what the numbers look like. The first quote is an anchor, not information Whatever the first shop comes back with becomes your reference point. If it's $18 and the market is $12, every subsequent quote looks cheap by comparison and you'll accept $14 thinking you did well. This is a real effect and it's well documented in procurement. The practical countermeasure is to send all RFQs on the same day, and not to open any response until you've collected all of them. Sounds bureaucratic; it changes outcomes. The spread between shops is mostly not about price When three shops quote $12, $14, and $31 for the same drawing, the $31 is rarely "expensive." Usually one of four things happened: They read the drawing differently. One shop assumed ±0.05 on the bore, another read it as ±0.005 because the note was ambiguous. They included something the others didn't. Material cert, FAI report, surface treatment, packing. They don't want the job. A shop with full 5-axis capacity quoting a 50-piece turning job is signaling. They made an error. Setup time estimated wrong, material price stale. Only one of those four is a price difference. The other three are information problems, and more quotes won't fix them — a better RFQ will. A 3× spread is a red flag on your RFQ, not on the market. Diminishing returns kick in around four The useful information from quotes is the distribution. With two quotes you have a range but no idea where the median sits. With three you can see if one is an outlier. With four you can usually tell whether the low one is credible or just optimistic. By the fifth quote, you're mostly learning the same thing again. The fifth and sixth responses move your expected value by a few percent while costing you another week of clarification emails. Four is the point where the marginal quote stops changing the decision. The real cost is clarification, not the quotes themselves Every shop asks some version of the same five questions: What material, and is the cert required? What quantity, and is that one lot or scheduled releases? Which dimensions are critical? What surface finish / treatment? Which Incoterm, and which port? If you answer those five in the RFQ package, response time drops from a week to two days and the quotes become comparable. If you don't, you'll spend that week answering the same email four times, and the quotes you get back won't be for the same scope. So the cheapest thing you can do is write the RFQ properly, not send it to more people. What a complete RFQ package contains For a machined part, this is the baseline: Item Why it matters 2D drawing with GD&T The 3D model doesn't carry tolerance intent STEP file Geometry, for CAM and stock calculation Material + condition 6061-T6 ≠ 6061-T651 for stress and price Quantity + lot structure 100 in one lot ≠ 4 × 25 Critical dimensions marked Saves the shop guessing which features to control Surface treatment spec Anodize type/color/thickness, or "none" Inspection requirement FAI, sampling, CMM report, or none Incoterm + destination EXW Shenzhen vs DDP Chicago is a 30% swing Target date Design freeze vs production launch changes urgency Nine lines. Fills one email. Turns four incomparable quotes into four comparable ones. When to quote more than four Three legitimate cases: Non-standard material. If you need Inconel 718 or a specific PEEK grade, most shops don't stock it, and their quotes include different lead times from different distributors. Four quotes on the material alone may not be enough. A process you can't evaluate. Thread rolling, EDM, vacuum brazing, passivation — if you don't know what the process should cost, more data points help you build a range. A first order with a new s...

Powered by Readybot.io

**DEV Community** ## How Many Shops Should You Quote? The …

DEV Community

GitHub Actions step output empty: the missing or misspelled step id

A GitHub Actions step output empty in a later step is a reference problem rather than an expression problem. The expression is valid, so nothing is rejected and nothing turns red; a property that is not there evaluates to an empty string, and every step downstream behaves as though the value was never set. Two conditions get a step into the context: it declared an id, and it has already run. Everything else reads back as an empty string. What this error means The workflow is valid, the run is green, and something downstream ran with a blank where a version, a tag or a path should have been. A condition gated on the value never fires, or fires every time, depending on which way round the comparison was written. A command receives an empty argument and either fails with a message about the argument or succeeds against the wrong target, which is the expensive version. Dumping the whole context is the usual next move and it produces the same puzzle in a smaller form: an empty object rather than a listing. Nothing in the log says why, because from the parser point of view nothing went wrong: it was asked for a property, the property was not there, and it returned what the documentation says it returns. ```Actions log, quoted from actions/toolkit#338 (timestamps removed) [group]Run echo "$STEPS_CONTEXT" shell: /usr/bin/bash -e {0} env: STEPS_CONTEXT: {} [endgroup]

Common causes

The producing step has no id

The common one, and the one that makes a context dump come back as an empty object. A step that writes to the output file without declaring an id has done the work and thrown away the label, so nothing can name it.

The id or the output name does not match

A rename on one side, a hyphen against an underscore, or a difference in case. The lookup misses and returns an empty string, so the workflow keeps running with a blank. Nothing compares the two spellings for you, which is why this survives review more often than it should.

The reference runs before the step it names

The context only holds steps that "have already run", so an expression in an earlier step, or in a job-level key evaluated at planning time, reads nothing. In our experience this arrives when steps are reordered and a condition that used to sit at the bottom ends up above the step that feeds it.

The step is in another job

A second job has its own context and cannot reach the first one. The value has to be promoted to a job output and read through needs, and a job that is not named in needs cannot read it even then, because that context holds direct dependencies only.

How to fix it

Declare the id on the step that sets the output

  1. Add id: to the producing step and use the same value in every reference.
  2. Keep the output name identical to the key written into the output file, including case.
  3. Put the reference after the producing step in the same job.

Print the value before you branch on it

One echo step tells you whether the output exists, which no condition can. Leave it in while you are wiring up a new output and remove it once the workflow is stable, or keep it behind a debug input if the output feeds anything expensive.

.github/workflows/release.yml (illustrative) - run: echo "meta.tag is [${{ steps.meta.outputs.tag }}]" Promote it to a job output for anything cross-job Declare outputs on the producing job, build each entry from the steps context, and read it from a job that names the producer in needs. This is also the only way to get a value into a job-level key such as runs-on or a job condition, neither of which can see steps. The producer below emits one JSON array, which the next fix expands into a matrix..github/workflows/ci.yml (illustrative) jobs: plan: runs-on: ubuntu-latest outputs: shards: ${{ steps.calc.outputs.shards }} steps: - id: calc run: echo 'shards=["1","2","3","4"]' >> "$GITHUB_OUTPUT"

Cast it back when you need a type

Because the value is text by the time anything...

Powered by Readybot.io

**DEV Community** ## GitHub Actions step output empty: the missing …

DEV Community

Reading a CMM Report: What the Numbers Actually Tell You

A buyer forwarded me a twelve-page CMM report last month with one line: "So does this part pass or not?" He'd had the report for two weeks. He'd printed it. He just couldn't tell what the numbers meant. That's normal. A coordinate measuring machine report is a technical document written for the person who programmed the measurement, not for the person making the purchasing decision. Here's how to read one in about five minutes. Start at the header, not the data The first page will have a block of parameters. Four of them matter: Temperature. CMM measurements are valid at 20 °C. If the part was measured at 26 °C and the report doesn't mention compensation, every dimension on a 100 mm aluminum feature is off by roughly 14 µm — which is larger than a ±0.005 mm tolerance. Not every shop logs this. The ones who do are telling you something about their process. Probe and stylus. A 2 mm ruby ball cannot measure into a 1 mm hole. If the report shows a small-hole diameter measured with a stylus that physically couldn't fit, the number is extrapolated, not measured. Program version and date. The report should say when it was run and with what program. A report dated three weeks before the shipment is a report about a different part. Datum definition. Look at which datum is primary. If the drawing says datum A is the large face and the report uses datum A as the bore, none of the position tolerances mean what you think. Then find the tolerance column, not the actual column People read CMM reports by scanning the "Actual" column and comparing to the nominal. That's backwards. Read the tolerance column first. It tells you what the shop thought you asked for. Then read actual. Then read deviation. The deviation column — actual minus nominal — is where problems show up, because a part can be inside tolerance and still be drifting toward one edge in a way that predicts the next batch will fail. If you see a column of deviations all positive and near the limit, that's a process trending out, even though nothing is out of spec today. Understanding what the columns are A typical line looks like this: Feature 12 Ø8.000 ±0.010 Actual 8.004 Dev +0.004 Out 0.006 OK
Nominal and tolerance from the drawing. Actual is what the machine found. Dev is the signed difference. Out (or "Out of Tol") is how much room is left before the limit. Sometimes shown as a percentage. Status is the pass/fail. For position tolerance, the number after ⌀ is a diameter zone, and the actual is usually reported as a diametral deviation, not a radius. Confusing the two is a common misread — a 0.02 position result is a 0.01 radial offset. GD&T modifiers change the answer Three modifiers show up constantly and each one changes the arithmetic: Ⓜ (MMC — maximum material condition). On a position callout, MMC gives you a bonus tolerance. If a hole is at ⌀8.05 when MMC is ⌀8.00, you get 0.05 of extra position tolerance. A report showing a position result that looks over tolerance may be perfectly valid once the bonus is applied. Check whether the report applied it; many don't, and the shop has to explain it manually. Ⓛ (LMC). Same idea in the other direction, used for wall thickness and clearance. Ⓟ (projected tolerance zone). Common on threaded holes. The tolerance zone starts above the surface, not at it. If the report measures at the surface, the result is meaningless. If the report doesn't state which modifiers were applied, ask. It's a two-line email and it's the difference between a real rejection and a misunderstanding. What CMM can't tell you Worth knowing before you reject a part based on a report: Small deep holes. Below about ⌀2 mm with depth over 5× diameter, the stylus can't reach the bottom properly. Reports may show a value that's really a partial measurement. Soft materials. Probe force deforms aluminum and plastics slightly. The measured diameter may not be the free-state diameter. Surface finish. CMM gives you geometry, not Ra. A separate surface roug...

Powered by Readybot.io

**DEV Community** ## Reading a CMM Report: What the Numbers …

DEV Community

Task Queue Retry Called The Customer Twice And An Exists Check Will Not Stop It

By Rokas Remeika. Published 22 September 2026. An at-least-once task queue retrying a telephony placement can ring a person twice, even if you check whether a call record already exists. This happens because the platform's native webhooks can create the call record before your dial RPC returns, and because a queue's retry timeout often fires while the first attempt is still ringing. To fix it, you need two markers. First, a post-placement marker written only by your dial code to prove the call happened. Second, a pre-placement attempt marker that locks the number for a window sized to your ringing timeout plus the queue's acknowledgment budget. Symptoms An at-least-once task queue retries the outbound dial task, and the same person is called twice within a minute. The queue metrics show only one logical task being processed, but the carrier logs show two distinct INVITEs leaving your infrastructure. The guard clause most people reach for (checking if the call record already exists before dialing) either never fires, or it fires on the first attempt and blocks a call that was never actually placed. The trap worth stating plainly: "does a record for this call exist" feels like idempotency and is not, as soon as more than one component can create that record. What is actually happening Two separate problems stack together to defeat a basic existence check. First, the call record is rarely authored by a single writer. The platform's native room-started webhook is fast and can easily create the record before the dial RPC returns. Because webhooks and the dial process run concurrently, the record existing is not evidence that a dial happened. An existence check in this state is simply reading a marker somebody else wrote. Second, the dangerous window occurs exactly between the moment we start placing the call and the moment we record the successful placement. Outbound ringing takes tens of seconds. A task queue that retries based on an acknowledgment timeout or visibility budget will re-enter the dial pipeline exactly during this window. Because the first attempt has not returned yet, nothing has been written to confirm placement. By definition, the existence check allows the second attempt through, resulting in a duplicate call. How to confirm it Log every queue redelivery of a dial task as an explicit event. This makes retries visible as events rather than being inferred from duplicate INVITEs. Correlate the webhook arrival time with the dial RPC return time for a single session. Expect to see the platform's room-started webhook arriving and writing to your database before the dial RPC completes its execution, proving that record existence is untrustworthy as an idempotency key. Measure the time from the attempt marker being written to the placement marker being written, per call. Count attempts refused by the in-flight window separately from attempts refused as already placed. How it works To prevent double-dials under queue retries, I use two markers with entirely different jobs. Relying on document existence is fundamentally flawed when multiple writers are involved. You have to pick fields that only the dial path can write, and check those fields exclusively. First, a post-placement marker serves as the final proof that a dial actually happened. This is written only by the dial path, and only after the placement RPC returns successfully. You check this field to know if the side effect is complete, never the bare document existence. Second, a pre-placement attempt marker closes the in-flight window. This is written immediately before firing the RPC. It acts as a bounded lock: any attempt that starts inside a specific validity window after an existing attempt marker is refused. I size that window to the 45 s ringing timeout plus the queue's acknowledgment budget. This guarantees that a genuinely in-flight attempt blocks a retry, while a dead attempt eventually releases the lock instead of wedging the phone number forever. En...

Powered by Readybot.io

**DEV Community** ## Task Queue Retry Called The Customer Twice …

DEV Community

Greenlight Counts Need a BigBlueButton Context Before They Mean Anything

Greenlight Counts Need a BigBlueButton Context Before They Mean Anything Greenlight is the end-user web interface for a BigBlueButton server. It handles accounts, rooms, meeting links, recordings, and the transition from a web session into a real-time conference. A ZoomEye count-only probe on November 15, 2026 returned 1 app="Greenlight" match, 1,108 title="Greenlight" matches, and 55,975 http.body="Greenlight" matches. The scope was sub_type=all, page 1, and page size 1. The title and body numbers are broad textual observations. "Greenlight" is a common word and appears in project names, marketing pages, and unrelated software. A single application fingerprint is a narrow signal, not a claim that only one Greenlight deployment exists. The useful next step is to establish whether a page belongs to a BigBlueButton frontend and what that frontend can control. The frontend is not the meeting server Greenlight and BigBlueButton can run on different hosts. The web interface may create a meeting and hand the user to a conference endpoint, while the media and recording services live elsewhere. Inventory both sides. A Greenlight login page without the associated BigBlueButton service is incomplete evidence, and a conference server without an identifiable frontend may still be reachable through a direct path. Review the BigBlueButton installation and Greenlight installation guides for the expected reverse proxy, TLS, and secret configuration. Confirm that the frontend uses the intended BigBlueButton host and secret. A test or staging frontend connected to a production conference server is a cross-environment authority problem. The application fingerprint can help separate a known Greenlight asset from generic title matches, but it should be combined with a response check. Use the page structure, login flow, and documented endpoints rather than inferring from the word alone. Account and room authority Greenlight can create local accounts and rooms. Public signup, guest join, room ownership, recordings, and administrative roles should be reviewed as separate permissions. A room link may be intended to be public. The administrator interface should not share that reachability. Test the invitation and join flow with an account that has the minimum expected role. Confirm that a user cannot change another room's settings or retrieve recordings outside the intended organization. Log room creation, role changes, and recording access with a bounded meeting identifier. Protect the BigBlueButton secret and any mail or single-sign-on credentials used by Greenlight. A web frontend that can create meetings may be less sensitive than the media server, but it can still disrupt classes, expose recordings, or send invitations to unintended recipients. Capacity and exposure The 55,975 body matches are far too broad to treat as a deployment population. They include the word in many contexts. The 1,108 title matches are still a discovery set. Filter by a verified Greenlight page, a BigBlueButton-related hostname, or a known deployment range before assigning ownership. Check whether a discovered host is a public demonstration, a documentation page, or a production portal. The official Greenlight project describes a free demo environment, so public examples are expected. A demo page should not be used as evidence that an organization's private meeting service is exposed. For confirmed services, measure availability and capacity separately from security. A reachable frontend that cannot create a meeting is not the same as a usable conferencing endpoint. A frontend that can create a meeting but cannot reach the media server may create a confusing outage without exposing conference data. What to record Record the Greenlight host, application evidence, related BigBlueButton host, TLS certificate, signup mode, guest join policy, recording retention path, and owner. Keep the ZoomEye observation timestamp and exact dorks with the evidence. Do not label title mat...

Powered by Readybot.io

**DEV Community** ## Greenlight Counts Need a BigBlueButton Context Before …

DEV Community

GitHub Actions reusable workflow input type mismatch

A GitHub Actions reusable workflow input type mismatch is the caller and the called workflow disagreeing about what a value is. workflow_call inputs are declared with a type and checked against it, so a quoted string sent to a boolean input, or an expression the typed key cannot accept, stops the run before any job starts. Three declared types, one list of contexts the with block accepts, and one cast for everything that arrives as text. What this error means One of two things happens, and they look nothing alike. The loud one is a validation failure in the caller: the run never starts, and the annotation names the input and the file it was not found in, or names the value it could not use. The quiet one is worse, because the run is green. A boolean input arrives holding text, the called workflow writes if: inputs.flag against it, and the condition is true whether the text says true or false, so a deploy that was supposed to be gated runs on every call. The tell for the quiet version is that toggling the caller changes nothing at all: the job runs identically with the flag set and cleared, and the only way to see it is to print the value rather than branch on it. ```Annotation, quoted from catalyst/catalyst-moodle-workflows#159 Invalid input, disable_phpcpd is not defined in the referenced workflow

Common causes

A quoted literal sent to a boolean or number input

YAML quoting decides the type before Actions sees it. publish: true is a boolean, publish: 'true' is a string, and the declared type is checked against what YAML produced. This is the version that passes validation in some shapes and then behaves as text inside the called workflow.

The value came from an expression, so it is text

Every step output is a string by definition, and a job output built from one is a string as well. Feeding it straight into a typed key gives you either a rejection or a truthy string, depending on where the mismatch lands. The cast has to be explicit because nothing casts it for you.

The with block reached for a context it is not allowed

Only six contexts are available in jobs.<job_id>.with.<with_id>. Referencing env, secrets or steps there produces an unrecognized name, and the typed key then rejects the whole value. Secrets have their own key, jobs.<job_id>.secrets, and that one does accept the secrets context.

The key is not declared in the called workflow at all

A rename on one side, a copied caller, or an input removed from a shared workflow. The parser is explicit about it, naming the key and the file: this is the one failure in the set that tells you precisely what to change.

How to fix it

Pass literals unquoted and let YAML carry the type

  1. Write true and false without quotes for a boolean input, and bare digits for a number.
  2. Keep quotes for strings, where they are harmless and sometimes necessary.
  3. Check the called workflow declares the type you think it does before changing the caller.

.github/workflows/ci.yml (illustrative) call: uses: ./.github/workflows/deploy.yml with: publish: true retries: 3 environment: 'staging' Cast expression results with fromJSON When the value comes from a step or a job output, wrap it. The cast belongs in the caller, at the moment the text becomes a typed input, and it keeps the called workflow honest about what it declared..github/workflows/ci.yml (illustrative) with: publish: ${{ fromJSON(needs.decide.outputs.publish) }} retries: ${{ fromJSON(needs.decide.outputs.retries) }}

Compare explicitly inside the called workflow

A condition that reads a bare input is only safe if the input really is a boolean. Comparing against the value you expect makes the job behave the same way whether the input arrived typed or as text, which is a useful property while a shared workflow has callers you do not control.

```.github/workflows/deploy.yml (illustrative)
jobs:
ship:
if: ${{ inputs.publish == t...

Powered by Readybot.io

**DEV Community** ## GitHub Actions reusable workflow input type mismatch …

DEV Community

How to get an EIN without an SSN or ITIN (Form SS-4 by fax or phone)

By OutsideFounder Team Originally published at https://outsidefounder.com/guides/ein-without-ssn. If you just formed a US LLC from abroad, the EIN is usually the next bottleneck. Banks, Stripe, and the IRS all want that nine-digit number, but the online EIN application expects a Social Security Number or ITIN. You do not need either of those. The IRS still issues EINs to foreign responsible parties for free, as long as you file Form SS-4 by fax or, in some cases, by phone. This is a practical walkthrough of the lines that matter, the correct fax numbers, realistic wait times, and what to do if the confirmation letter never arrives. It is general information, not tax or legal advice. Rules can change; confirm details on irs.gov. Facts below are current as of 15 November 2026. Short answer: On Form SS-4, enter Foreign (or N/A) on line 7b. If the LLC has no US place of business, fax 304-707-9471 from outside the US, or 855-215-1627 from inside the US. If you listed a US street address as the place of business, fax 855-641-6935 instead. International applicants with no US place of business can also call 267-941-1099. There is no IRS fee. The IRS says fax applications take about 4 business days; founders often report 1–6 weeks. Key facts Item Value Source IRS fee for an EIN Free IRS – Instructions for Form SS-4 Fax, no US place of business (from outside the US) 304-707-9471 IRS – Instructions for Form SS-4 Fax, no US place of business (from within the US) 855-215-1627 IRS – Instructions for Form SS-4 Fax, US place of business 855-641-6935 IRS – Instructions for Form SS-4 Phone, international applicants 267-941-1099 (Mon–Fri, 6 a.m.–11 p.m. Eastern) IRS – Instructions for Form SS-4 IRS-stated time by fax About 4 business days IRS – Instructions for Form SS-4 Before you start The LLC must already exist: you need approved Articles of Organization. Have the exact legal name, the formation date, and a mailing address ready. Choose the responsible party: the individual who ultimately owns or controls the LLC, usually you. You need a fax number that can receive a reply. An online fax service is fine. If you are still deciding whether an ITIN is required later, see our separate EIN vs ITIN guide for non-residents. An ITIN is not a prerequisite for this EIN application. Filling in Form SS-4: the lines that trip people up Download the current revision from irs.gov/FormSS4. Line What to enter 1 The LLC's exact legal name, as on your Articles. 4a–4b / 5a–5b Mailing address, and the physical street address only if it is different (no P.O. box on 5a). For an address outside the US, write out the country name. The address you give affects routing. The international fax and phone numbers are for entities with no legal residence, principal place of business, or principal office in the US. A US street address as the LLC's physical location points you to the domestic fax 855-641-6935 instead. 7a–7b Responsible party's name. On 7b enter Foreign or N/A if they do not have, and are not eligible for, an SSN or ITIN. An entry is required. 8a–8c Yes, it is an LLC; number of members; formed in the US. 9a Single-member, foreign-owned: check Other and write Foreign-owned U.S. disregarded entity-Form 5472 (the IRS wording). Multi-member: Partnership, unless you elect otherwise. 10 Foreign-owned single-member LLC: check Other and write Foreign-owned U.S. disregarded entity filing Form 5472 (the IRS wording). Otherwise, use the reason that applies (for example "Started new business"). Signature Sign, date, and add your phone and fax number so the IRS can fax the EIN back. Those Form 5472 labels on lines 9a and 10 are about how the IRS classifies a foreign-owned disregarded LLC. They do not file the annual Form 5472 for you; that is a separate yearly filing. Three ways to apply Fax (most common) The IRS chooses the fax number from the entity's location on lines 4a/5a. No legal residence, principal place of business, or principal office or agency in a US state...

Powered by Readybot.io

**DEV Community** ## How to get an EIN without an …
